Jekyll2026-10-06T22:54:02+00:00https://www.frank.computer/feed.xmlFrank ElavskyAssistant Professor of Data Science investigating accessibility and data interaction. Previously: PhD from CMU, data interaction R&D at Adobe, Highsoft, Apple, Visa, + others.
Skeleton wins best paper at IEEE VIS 20262026-10-05T00:00:00+00:002026-10-05T00:00:00+00:00https://www.frank.computer/blog/2026/10/best-skeletonMuch to my absolute shock and surprise, I received an email just over two weeks ago that the project I led as the final stage of my thesis work, Skeleton, won best paper at IEEE VIS. This is, of course, one of my greatest achievements and easily the greatest professional recognition I’ve received so far in my life.
First off: Skeleton gets a win during spooky season? My favorite time of year? Incredible personal victory.
(Before I blog any further, you’re welcome to learn more about our project Skeleton over on the other post I blogged once we learned it was accepted at VIS a little while back. This blog post is not an introduction to the project, so consider yourself warned that adequate context about the paper will not be provided here, heh.)
Now, the first actual thing I want to say in this blog is that I don’t really take the “best” part of “best paper” too seriously. In fact, I used to think it was a bit problematic. If we are judged based on the merit of our work, what are the criteria? Why is the process never transparent? Why do we even have these awards? Why make something into a race that wasn’t to begin with? Well in this meandering blog post, I unpack a bit about how my thoughts have shifted on best papers over the years. Nowadays, I’m convinced that they do a net good for the receiver (duh) as well as the community. The latter part is the bit I really care about.
Some context on VIS
I love the visualization community, both academic and not. And I started out in a small slice of the academic world of things back in 2015, doing a visualization REU at Clemson University (which was also my introduction to Digital Humanities as a field of work). Books by Munzner, Cairo, and Drucker filled me with inspiration. A satisfying and rewarding little industry career kicked off after that before I started my PhD in 2021 to focus on visualization and accessibility. I connected with both academics and industry folks all over the world thanks to Twitter in the late 2010s (RIP), many of whom are now good friends, colleagues, and co-conspirators.
To say that a best paper award at VIS is an honor really is an understatement. A while ago, I wrote down several bucket list items like finishing my tabletop rpg, writing a few books, paying off my student debt, and quite specifically, getting a best paper award at IEEE VIS. I figured each of these would take a decade or two (or more) to pull off. I’m frankly shocked that I’ve at least got one of these checked off so early in life.
But I’d like to take a moment to explain a few things now to folks who might not be savvy on what VIS is. VIS, short for visualization, is our premier academic conference. And to some academics, a conference isn’t really a big deal. But in the computer sciences, and visualization being included among them, we do our main peer review and publication work through our conferences. A full paper accepted at VIS is a feat on its own (generally <25% acceptance rate). This is where we send our best.
Doubts about myself, my doubts about “best”
I had struggled with impostor syndrome for years. I didn’t feel welcome or remotely like I belonged in academic spaces. And to some degree, I really am a terrible academic. Or, at least I am a really atypical one. Skeleton is a testament to this, actually. It’s not a standard research paper. It’s a long-running quest to build first, research later. That is far too risky for a standard academic path. On the one hand, we really knew what we wanted to build before we did any industry work. We knew we wanted some kind of visual interface for crafting non-visual experiences. But the texture of what this kind of interface looks like, how it operates, what questions it asks of us, and (more importantly), the empirical evidence that justifies it, was all missing. I wasn’t a good academic in the process. I was chasing building and making before really having a plan put together. It was, at times, a mess. Dominik and Patrick put up with my nonsense for years. I pretty much did whatever I wanted, a terrible PhD student and employee, really.
I certainly wouldn’t expect a PhD student to have done what I did. I wouldn’t want replication of our work. Far too risky, expensive, slow-moving, and so on. Perhaps, to some degree, this is why it won “best paper” (I’ll unpack this a little more later).
Yet at the same time, while a best paper award is a massive honor and I truly don’t feel like I deserve this kind of recognition (nor does my already-massive ego need any additional ammunition like this), the “best” in a best paper award never sat well with me. In general, I find recognitions like these to be strange and alien to comprehend (at least in principle). But a few years back, Zong, Lee, and Lundgard won an honorable mention for Rich Screen Reader Experiences (truly a masterpiece paper that I could talk about for hours). And to me, yes, this was the best paper at EuroVis. In some ways, I wish it won “best” and not just “honorable mention,” but it occurred to me that I should stop thinking about some atomic moment where papers are measured based on merits and instead think about the social role that papers play.
What “best” really should be about in a best paper
And so I think about a council of wizards, folks who know and care about a field of work and have dedicated decades of their life to it. When this council points at a paper and says, “this one is the best,” they are saying far more than simply “the merits of this piece are better than others.” What they want to do is call attention to excellence. In particular, they want their field to pay attention to not only an exemplary piece, but one that they believe will push the boundaries of the shared space they inhabit with their peers. Derya’s utterly fantastic paper on operationalizing feminist theory in visualization is perhaps my favorite example of this. The judges knew what they were doing when they gave it a best paper award. Our field needs to pay attention to it. It is paradigm-shifting in many ways.
A good council of wizards understands that “best” isn’t useful on its own. But by recognizing the work of others and elevating specific papers and projects, we might inspire new directions. The award then doesn’t serve as a backward look at something that has completed and is over, but is using completed work as a hopeful look forward, towards what could be.
A “best paper” isn’t just a signal of faith in a single artifact, but a signal that the stewards of our community have faith we will all figure out what to do next. I think that is beautiful.
And this is why I am honored to receive a best paper award. Not because I even remotely care about being the “best” in terms of some opaque measure of merit, but because winning this award is a deeply hopeful recognition in the value this piece might have to offer our field. I’m humbled that my peers would think this. And in some ways, baffled. I really don’t know if I’d encourage someone else to repeat what I’ve done. But I do hope that more work directly with practitioners happens (which is also why I’m happy to be chairing Cluster a one-day practitioner’s summit at VIS this year). I also, of course, hope that visualization offers itself up to serve the problems of accessibility more than it does. I opened the paper with this “provocation” and I certainly still mean it.
Thinking now a bit about Skeleton and what I’d want the community to do with it
During my PhD, visualization was so concerned with solving accessibility and borrowing from the practices and problems of accessibility, that I feel like it forgot itself for a moment. Visualization has plenty to offer back. I love the richness of our projects on interactivity and tool-making in particular. And I also even hope that the shared work of grammars, infrastructures, performance, and many other little things we seem to care about in visualization can trickle over into accessibility’s domain as well.
But my final note is this: I left industry to explore how the heck we can motivate people to actually do accessibility work. Chartability was step one. That’s checklist-style accessibility; imperatives, guidelines, and heuristics. But that only gets you so far. Real “designerly” thinking, where you wrestle with highly complex problems (some of which may be impossible to solve in a single interface, as we argue in Softerware, which will also be presented at VIS this year), feels impossible to motivate in people. I really did leave industry because of this. It seemed like HCI was the path I needed to investigate. I had to know more about why people make the decisions they do and how we might be able to introduce technologies that can shift their behavior.
Good news, Skeleton is some evidence towards this sort of shift.
But as I argue at the end of my thesis, I really think that tools and technologies only take us so far. Checklists get us some of the way. Tools-as-interventions, a little further. But we can’t tool our way out of broken priorities, lack of funding, unenforced policies, or dysfunctional federal support. Even so, it gave me just a touch of hope to see that visualization did seem, to some degree, to give practitioners a material to respond to. Did they design good designs? Likely not. We didn’t evaluate that. But did they demonstrate the signature behaviors of design? Iteration? Reflection? Deconstruction? Yes. I’d love to see more work like this down the road.
To write a paper where we argue that people who are sighted might be the ones who face sensory barriers to access felt nearly absurd. But when you work enough with visual people, you realize that they think visually, write visually, and speak visually. Their tools and languages are visual. Their materials are visual. It stands to reason that their thinking and reasoning is too. Is it an equity and justice issue that we are (yet again) recentering visuals in design? Yes. But I don’t know if we can expect someone to communicate, design, and think in modalities that they haven’t spent years in already.
The next steps beyond this work will be interesting to see. Do we use visual language to help sighted practitioners first translate and then begin to think in ways that center non-visuals? Do we lean further into visual authoring? Do we explore how quality shifts and changes? Do we look at false assumptions, mistakes, and problems that arise when non-visuals are translated into visuals for design work? Probably yes to all of these. I’d love for my peers to tackle these questions (and more).
In any case, thanks to my community for putting up with my nonsense for years. I appreciate that my paper has been held up as a piece for others to look at, inspect, critique, and build off of.
I look forward to seeing many of you at VIS. I hope you can make it out for my talk, and perhaps chat with me after.
]]>Does human-computer interaction research enable anti-social practices? Does AI make this worse?2026-09-15T00:00:00+00:002026-09-15T00:00:00+00:00https://www.frank.computer/blog/2026/09/anti-social-hciThe click-baity idea I am stewing on here is basically this: do people actually really hate learning about other people?
The inclination I’ve picked up over the years is that business-minded folks seem to loathe the “requirements gathering” and “discovery” phases of research especially, where early ideas are shown to potential users or perhaps highly important users to consider, such as people with disabilities. And there is a general vibe, a bit hard to describe, where the business folks (what you might call the “product owner” whose idea has spawned some new spinoff or product or software or service) seem to really hate involving users. My conjecture is that folks who have some kind of vision often want to be held accountable to nothing, if they could have their way. And if they could have their way, they’d also make things according to their own interests and tastes.
And yet human-computer interaction research, in both industry and academia, hinges on this fundamental gap that people tend to have in their “local” (eg “personal”) knowledge: that other people probably don’t agree with you on everything.
Now, I’m going to talk about two things in HCI research that are both “anti-social” in a way. One is good. The other? Worries me.
HCI research is anti-shithead
So one of the best ways to reign in an absolute spreadsheet of a human, someone who really only cares about whatever little thing they’re on about, is to run a study that demonstrates not only how their core idea is lacking but also ways that their core idea could improve. And to some degree, this is social. That is to say, the HCI research acknowledges that something is better when we learn about more people and perspectives and so on.
But it is also anti-social in a sense, because it fundamentally doesn’t trust some singular person to have a perfect vision and perfect execution. We need to test ideas rigorously. And we do that by involving others. So to the “product owners” at the top, it’s a bit anti-them (or at the very least anti-dictatorship). From the perspective of a terrible person, that might seem anti-social. It’s all about perspective of course, but worth noting. I think that anti-shithead is a good kind of anti-social. We can’t always be fully inclusive, especially of someone who wants everything to go their way. We’d be even more anti-social if we let a singular person have full reign over the things we create and build.
HCI research also enables alienation
The real idea (the spicier one) that I wanted to write about here is how human-computer interaction research is actually, unfortunately, a precursor to something that AI also does: it alienates people.
When you have good and genuine builders and makers, they’ll rightfully want to connect to the real people who are affected by the systems, tools, technologies, and policies they are building. However, as I know full well from accessibility work in particular: many people do not want to actually work with people with disabilities (or give them any power).
And here comes HCI research. HCI research, practically speaking, often operates in a way where power can be maintained by the builders and makers because knowledge-production is made into a separate, “neutral” activity that is conducted by specialists. Does it always work this way? No. But does it mostly? I would argue, yes.
HCI researchers are specialists. They stand between people, such as people with disabilities, and the system owners, technology builders, and so on. We have become mediators of knowledge, but that knowledge is only extracted unidirectionally. And this is, by its asymmetrical structure, a power imbalance too.
This pattern, of a thing put between things in order to create power imbalances, is fundamental to many systems of power: authoritarian governments, bureaucracies, HR in the workplace, and capitalism in general. The best capitalist ideas aren’t ones where someone makes something new or “wins” a rat race beating people in a fair fight, but where a gate can be built between things where people otherwise would have fluidly moved freely. Crossing a bridge? Tollbooth. Healthcare? Insurance. Spending money? Credit cards. And so on. This separation between people and people (and also between people and things) is alienation.
HCI researchers interact with people and translate what they find to people in power because people in power don’t want to do this work, and certainly don’t want to do it themselves. In this way, HCI research alienates builders and makers from other people and alienates people from the builders and makers.
And lo and behold: the once-human-to-human practice of HCI research has now been ursurped by prompting and multi-million dollar startups that claim to have crowds of human-like (and post-human-like) agents who can scale knowledge extraction, albeit via simulation. The core idea claimed is that this method is even better than working with humans.
And because HCI research is simply imagined and envisioned as a vehicle for extracting knowledge from an “other” and bringing that into the work that a person or company is doing for themselves, then a way to get more knowledge, in a bigger format, even faster is obviously an improvement. HCI research, in this framing, was a stepping stone towards synthetic knowledge production at scale.
HCI research was set up as a fragile operation from the start: we didn’t have the power. We acted on behalf of the people with budgets and money and so on. And the people we work with certainly rarely have any power either. And because our job was to act as a knowledge-extractor for systems of power, HCI research in the workforce is at risk of being prompted away.
But… is knowledge extraction really all that HCI research is actually good for? And even if we stick to the core framing of research-is-for-knowledge, we need to interrogate who the knowledge should be for. And in order to do that, we need to pay close attention to the framing and motivation (and even funding) that underpins all of HCI (and especially our own personal work and agendas).
What do we do?
Well, there is a broad and deep collection of sub-disciplines, practices, methods, and people who don’t do HCI research in this purely extractive company-edifying way. Are these people and methods employed in industry settings? Not many that I know of. But do they demonstrate a more-hopeful vision of what HCI research has been and should be about? Yes.
One of my favorite introductions that I suggest folks read is a primer on disability justice in HCI research by Sum et al. It’s fantastic and just the absolute tip of the iceberg on this topic. Disability justice, as just one example of many, completely flips and reframes what should motivate our collective work.
In my humble opinion, the core way that HCI research should operate is disruptive. It should be a way for people who may not have power to now have a say, a seat at the table, and perhaps even budgets or staff who work to make their lives better. Synthetic agents don’t require any power at all! Which is why those ideas, as replacements for HCI research, are deeply perverted, anti-social, and alienating.
HCI research can and should operate as ways to hold people accountable who have power, disperse and distribute power, and even enable more radical alternatives to building and making things. HCI research isn’t really about making better products. Products are always a proxy for some other function or process in our lives. So HCI research should be about living better lives. HCI research should be about the redistribution of knowledge for everyone, and not just a concentration of knowledge handed to corporations and systems that already have immense resources.
Do what I call “robin-hooding” HCI
And yes, in my own self-awareness I recognize that HCI research is essentially an arm of the tech industry, even in academia! My own funding has largely been thanks to companies (Adobe, Apple, Highsoft, and so on). But if companies fund me to do my work and they’re happy with the outcomes, isn’t it alright if I am leveraging those funds to do a little bit of care-filled infrastructure-building and maintence work, too? Or to put this in analogous terms: If we could convince Microsoft to fund public roads, no strings attached, I’d argue we have won some decisive battles.
I call this style of reseach “robin-hooding:” you convince budgets that would otherwise go to something harmful, problematic, profit-serving, or virtually useless to go towards work that is necessary, good, and foundational: care and repair. In my own work, my vision is for every data visualization library to become accessible someday. I left VISA to do this work. I did this during my PhD. I am still doing this work today. I believe that every person who lives with a disability and has to interact with charts and graphs that exclude them, deserves better. So for me, I need to find ways to (as I say) “get away with it:” that is, convince people in power to pay me (and others with disabilites) to fix their broken systems.
And on accessibility and interfaces: The tech world around us is a new kind of infrastructure. It isn’t publicly-funded roadways. It is massively silo’d, closely regulated little fiefdoms of privatized software and services. Unless we have a radical revisioning of how all of tech works today, each individual company has to fix their own broken roads (figuratively speaking). And I do this work by getting money from tech companies and then contributing (as best as I can) through open source channels.
There’s plenty left to do! Plenty more robin-hooding to be done. And for me, I focus on care and repair. Perhaps you, my reader, imagine other futures and outcomes and dreams that you want to pursue. I’d encourage you to dream of how HCI research can help you along that path.
HCI research is a fundamentally social practice that has been co-opted to enable anti-social systems of power. Time to take that back and return to the anti-shithead, knowledge-for-all roots of our work.
]]>How to disable generative AI in python notebook environments (ipynb)2026-08-25T00:00:00+00:002026-08-25T00:00:00+00:00https://www.frank.computer/blog/2026/08/disabling-genai-autocompleteThis guide has come about from a simple problem: notebooks that I inherited for teaching Introduction to Data Science in python to undergraduate students all now have generative AI turned on by default in Google Colab. This short guide disables generative AI in ipynb files (which can be used in a variety of environments but this solution only works for Colab).
I won’t dig too much into why autocomplete using generative AI is counter to learning fundamental concepts. If you don’t agree with me on that, I’m not using the real estate of this post to convince you otherwise. But for fellow data science educators who come here to this post, below is my solution for creating a single notebook that students copy into their own environments, which will have AI disabled by default for them. You’ll still want to tell students (especially if there is a course policy against generative AI use) that they still need to check where to turn off these features if they, for some reason, still see them (this is especially true if they use a local environment out of VS Code or equivalent instead of Colab).
And to be clear: The way the below solutions work is because I expect students to take my existing ipynb files and copy the file itself into their own Colab environment. If students copy cells from an open notebook into a notebook or environment of their own, this solution will not work. The simple thing we are doing here is disabling generative AI in the metadata section of the ipynb file, which will be carried into any new Colab environment where that file (or copies of that file) propagate.
{"nbformat":4,"nbformat_minor":0,"metadata":{"colab":{"provenance":[{"file_id":"1IqPnGOHsS5XV49SeB7Bgza91pOAK9Ztc","timestamp":1787760836099}],"generative_ai_disabled":true},"kernelspec":{"name":"python3","display_name":"Python 3"},"language_info":{"name":"python"}},"cells":[{"cell_type":"markdown","source":["## Cal Poly, San Luis Obispo\n","\n","## DATA 3301: Introduction to Data Science\n","\n","\n","### Lecture 1: Notebook Zero"],"metadata":{"id":"1ON93brE4GD8"}},{"cell_type":"markdown","source":["## Before You Do Anything Else!!!\n","\n","**If you are viewing this notebook on Google Colab**:\n","\n","This is the Instructor's version of this notebook. Any changes that you make cannot be saved and will be lost when you close the browser.\n","\n","If you want to add code or modify the contents of this notebook in any way and save your work, **you need to save a copy of this notebook** to your personal Google Drive. To do this, go to File > Save a copy in Drive.\n","\n","**In fact, this should be the first thing you do whenever you open up a notebook that someone shares with you.**"],"metadata":{"id":"lygz8K1J4WWt"}},{"cell_type":"markdown","source":["# Notebooks Consist of Cells\n","\n","## There Are Two Main types of Cells:"],"metadata":{"id":"oB7_MKKiJjo9"}},{"cell_type":"code","source":["## Code cells let you write and execute Python code\n","\n"],"metadata":{"id":"ooRyI1AzJ4bw"},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":["\n","## Text Cells let you write text\n","\n","... and use mathematical formulas:\n","\n","$$ distance(x,y) = \\sqrt{\\sum_{i=1}^n (x_i - y_i)^2}$$\n","\n"],"metadata":{"id":"uDWQN8XaJjrU"}},{"cell_type":"code","source":[],"metadata":{"id":"JBDeJoapJ0gu"},"execution_count":null,"outputs":[]}]}
If you open your file and add this, you’re good to go!
Option 2: Disabling using Colab’s interface
The other way to get to this setting is how I initially found it, which was through Colab’s own settings (once I opened the file). This is also a great way to quickly verify with a student if their current notebook has genAI turned on.
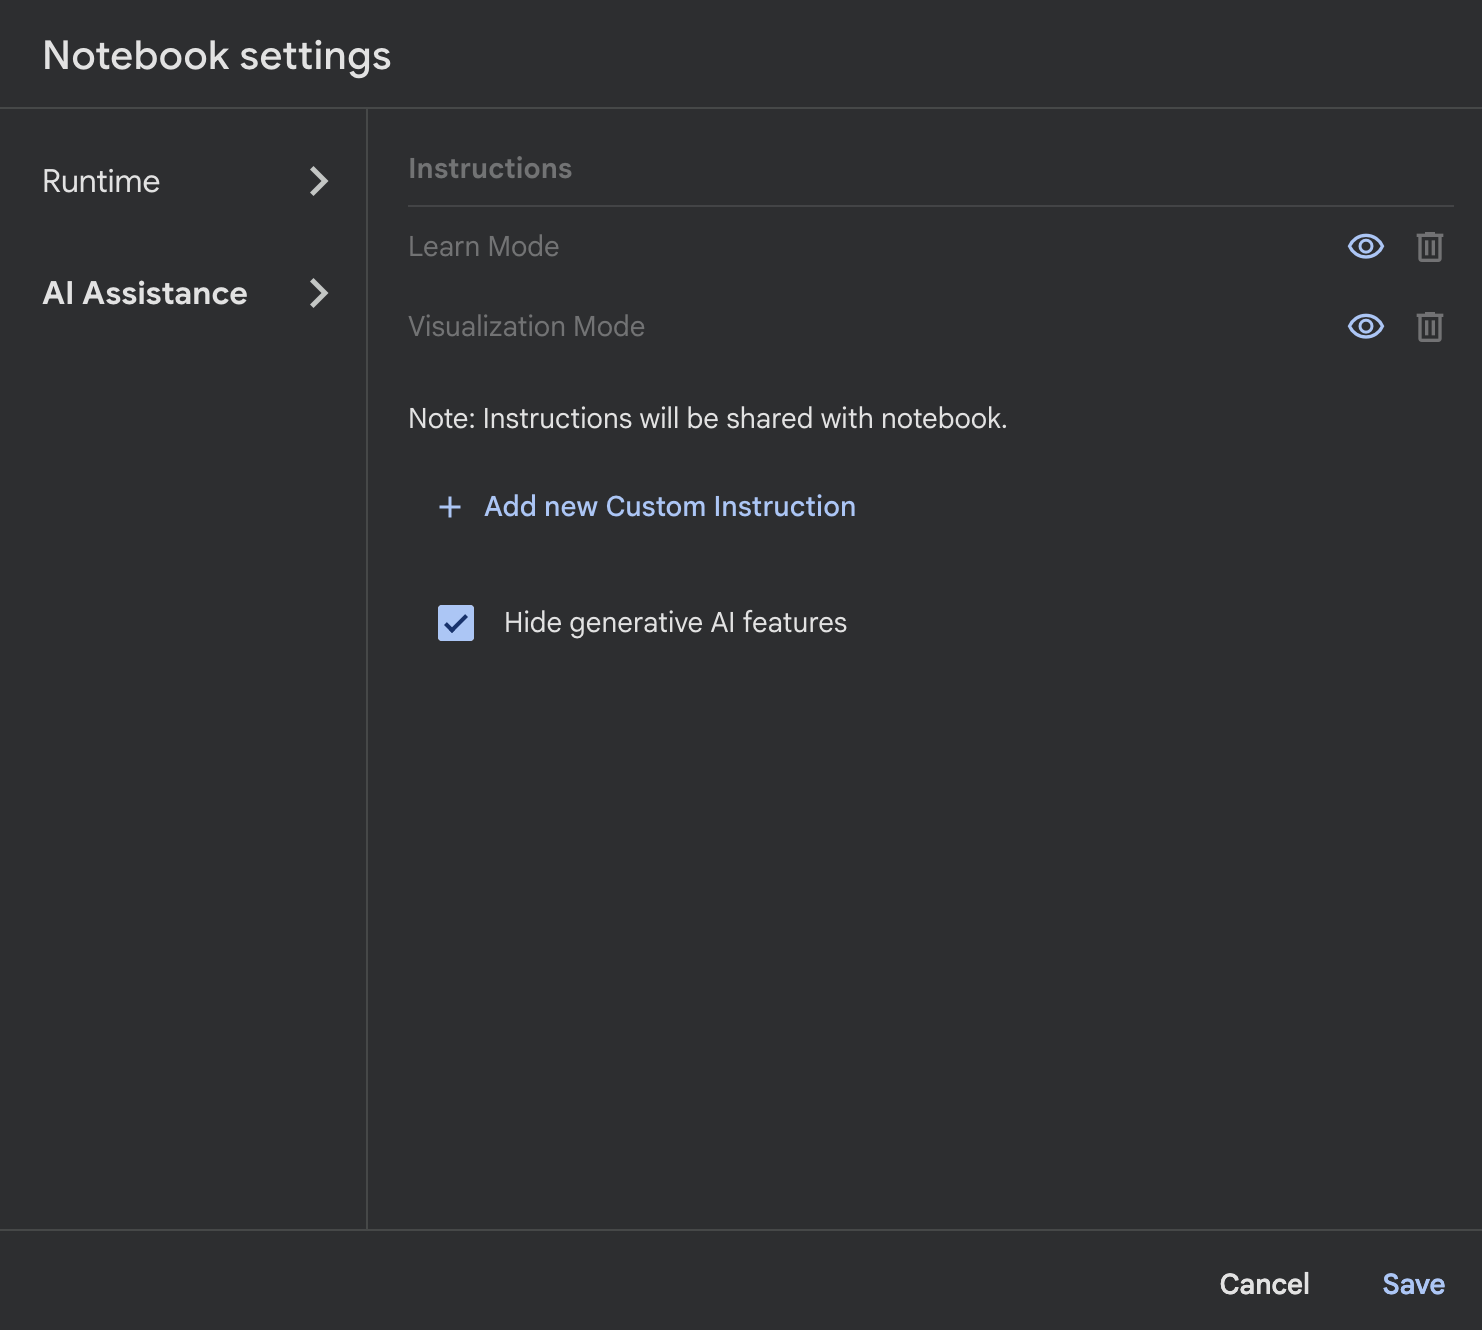
Edit > Notebook Settings > AI Assistance > ✅ Hide generative AI features
Colab's interface for disabling generative ai features in a specific notebook.
Once you set this and the file is saved, the metadata (from option 1 above) is populated into the file. Now, students who copy the file (using File > Save a copy in Drive or simply by copying the actual ipynb file itself via downloading, copying, or otherwise) will get this setting too.
A new age: refactoring against Gen AI for the sake of student learning
The great thing is that we can easily populate this metadata property into every ipynb file used as course materials in Colab (assignments, in class labs, my lecture note-notebooks, etc), which is fantastic. The frustrating reality is twofold: one, that students can easily turn this back on or use another environment (not much I can do to stop this) and two, that the feature was simply added in silently as opt-in. Rather than a lack of generative AI being treated as the default state, now every single notebook opened in google Colab will have this turned on by default.
Should I migrate away from Colab? Perhaps. The dream is that every student has a fantastic personal machine and we get them set up with local environments of their own. But the reality is that the cloud computing part of Colab is still useful, as well as the general integration in Google’s ecosystem. (So should I swap to Jupyter? Maybe! But for now, sharing google drive links to my saved files and having them open by default in Colab is so painless of an experience that for an introductory course, I’ll be sticking to Colab. Ironic though… some parts of learning should be good pain while other pain I actively work to take out of the educational experience.)
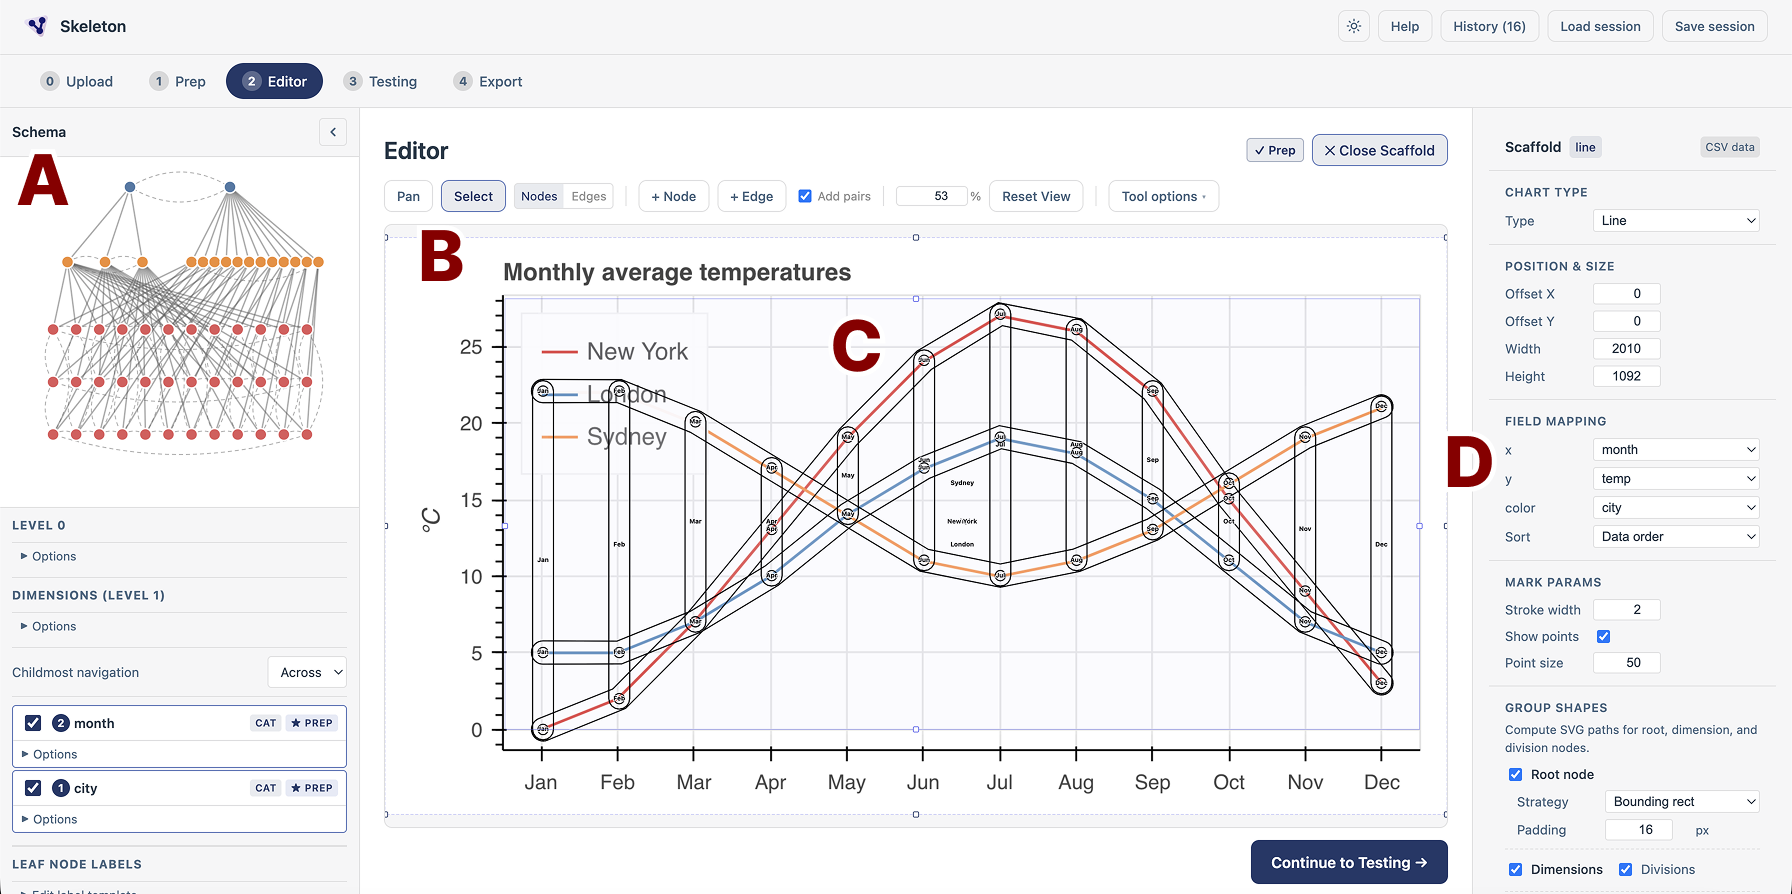
]]>Announcing: Skeleton 🩻, the culminating project of my PhD!2026-07-18T00:00:00+00:002026-07-18T00:00:00+00:00https://www.frank.computer/blog/2026/07/announcing-skeletonSkeleton being used to build a navigation structure over a line chart. A: a dual tree visualization of nodes and edges built for a line chart with 3 lines, spanning over 12 months. B: a direct-manipulation canvas that resides over a static png image of a line chart. C: a skeleton-like structure of nodes, edges, and group outlines that correspond to the schema shown in (A), overlaid on the visual space of the chart in (B). D: controls for rapidly scaffolding the nodes, edges, and their shapes shown in (C), using Vega’s visualization engine for automatically generating spatial properties.
The final project of my PhD, titled “Skeleton: Visual Authoring of Non-visual Data Experiences” has now been fully accepted at IEEE VIS 2026. Woohoo! (You can check out the pre-print of the paper at this link.) Depending on who you are, my reader, this announcement means different things. To my fellow academics: this is great news! VIS is the premier venue for visualization research. This will be a fantastic opportunity for me to share my work and findings with other researchers. I look forward to future chats with you all!
But for my fellow practitioners, why does this matter? Well, our paper outlines this a bit more (and if you’ve never read an academic paper, give it a shot!), but we oriented our work as action research. That means that our technical projects (the things we built) were grounded in work with practitioners. Our work was relevant to them, so I hope to you my reader, it will be relevant too.
Yet before I jump into a bulleted list of TL;DR takeaways, I desperately hope that whoever you are, an academic, practitioner, or someone random, that you will stick around at least for my short pre-requisite introduction to this topic first.
But here is the bulleted list of takeaways:
Sighted people face barriers when authoring non-visual data experiences
We built a tool to visualize the data structure used to make charts and graphs navigable
We built a tool that mirrors the grammar of graphics, but focuses on non-visual navigation dimensions in charts and graphs
We then built a visual user interface that makes it so that a user can directly manipulate non-visual data experiences they are authoring as well as test their experiences
We also had some fun with heuristic-based (non-ML) computer vision and some other neat tricks to make scaffolding navigation experiences as fast and easy as possible
Lastly, our study revealed quite a lot! But our most important finding was that sighted practitioners treat non-visual experiences as equal to visuals once they can see and manipulate them. They iterate independently and substantially once they can see a design element, they treat non-visual experiences as a complex and serious space of design, and they even iterated on their visual design choices once they understood how their visuals might influence the non-visual experiences people will have of their charts!
A brief introduction: What is wrong? What matters? Why accessibility and visualization?
I finally articulate and unpack why I do this work, in length, in my thesis (which is now out in the world, officially). If you want a deeper dive, check it out (or my smaller baby thesis sub-docs).
But people who live with disabilities deserve to live full lives. They deserve to participate in their communities, in our world, in the politics that affect them, in political and civic action, in well-paying jobs, in decisions about their healthcare, and in staying informed about matters like the economy, their personal finances, academic research, local news, and more. And in our world, interacting with and being able to communicate with information is an important part living a connected, happy, healthy life. People with disabilities deserve to have access to data.
And yet, the problem is that people with disabilities are often not considered when software and hardware are designed. Ultimately, this means that simple access to information for someone who is sighted becomes a tedious, time-consuming, painful chore for someone who is blind. And most often, people are fully excluded from access due to how we have built our technological world.
But things don’t have to be this way. We can build things better. We can make our websites, tools, software, applications, and devices more accessible for people with disabilities.
And the good news? To some degree, people have been doing this work. This field of work is called “accessibility” work. And some people specialize in it (it is their whole thing) while others integrate it into the work they do (such as people who make data visualizations but understand how to make them more accessible or leverage tools that help them do this work.)
These people, this subset of “practitioners” who work, or want to work, on accessibility related to data interfaces are the people I set out to work with in this research project.
My sighted collaborators struggled to work with non-visual design materials
We collaborated with 3 different groups of practitioners, with varying degrees of involvement in the design or development work that they were undertaking, related to making visual representations of data more accessible to people with disabilities. Our collaborators were primarily sighted, although we did also have blind co-designers who joined us in those collaborations (or who specifically helped us with our later work).
Part of the work of making visualizations accessible is making them navigable for people who use assistive technologies. Some assistive technologies that navigate might include screen readers, keyboards, voice controls, “switches,” sip and puff devices, and more. My past project (linked above), “Data Navigator,” focuses on making this translation work possible. Designers and engineers can work to create non-visual and visual navigation and interaction experiences with data structures.
However, doing this work is quite hard. Our collaborators iterated heavily in visual design tools. They used visual, diagrammatic markers and artifacts to iterate on their ideas. “If we place a navigation node here, would could navigate over to here” they might say, while laying a circle object over the first thing they’ve referenced and then dragging out an arrow from that circle onto a new area of our design space. Our collaborators reasoned about the spatial structures and experiences of their imagined end users in visual metaphors and symbols.
And yet, building these structures (enacting these designs in real, working prototypes) involved working entirely in code (in text) without any visual representation of what they were doing. Testing the designs required interacting with non-visual structures using non-visual tools: loading up a screen reader and stitching together the resulting prototype’s performance interactively, one piece at a time. Testing was not only manual, but also non-visual. This work became quite tedious, prone to errors, and difficult for our fellow practitioners.
Discovering inaccessibility for people without disabilities
We needed to improve the debugging process. And the first step was recognizing that we should probably visualize the data about the system’s structure. Ironic! We are trying to make visualizations more accessible for people who are blind. To do that, we need to make non-visual experiences that can make our visualizations (or their underlying data) more accessible. Yet, because those experiences are non-visual… they are inaccessible to our sighted collaborators!
In the social model of disability, which is a framing that can sometimes be quite useful, we talk about how our created world (be that curbs on our sidewalks, the politics that govern us, or our software) produces barriers for people with disabilities. Those barriers are where a person who has a disability actually experiences that disability. (Again, note that this framing isn’t complete, but it is useful.) What this means is that because we have brought artificial things into the world and those artificial things are now holding some people from participation in the world, it is up to us (the creators) to fix these things.
The social model is useful because it helps us orient who is responsible, who needs to be included, and so on. Great!
But in the social model, the most interesting thing is actually that disability is produced between a human and an interaction with something else. A person in a wheelchair becomes disabled (unable to participate in navigating their city) when a curb blocks their path.
Now, in our research project with Skeleton, we demonstrate that even sighted people can face barriers when working with non-visual design materials. A software system, when inadequately designed, can disable anyone.
Introducing: Our “Inspector” gadget
To address this first issue, we built a simple tool for visualizing the structure under the hood. We call this our “inspector” and also built in custom console menu based on our collaborative work. We figured that the first pre-requisite for any future iterations will require being able to see what navigation looks like.
The inspector simply shows a developer what the system “sees:” which nodes exist, and how they are connected to each other through their edges. Interestingly, there isn’t too much precedence for this in terms of accessibility. Web sites don’t expose the accessibility object model and structure, and therefore it isn’t easy for a developer to gain a visual sense of how and where screen readers or assistive technologies will navigate, when navigating on a webpage. This is a huge issue! (So even outside of the scope of our research project, we hope that this catches on in the coming years and we can soon see screen reader and non-screen reader navigation visually over a webpage, when opening the developer tools of a browser. One can dream!)
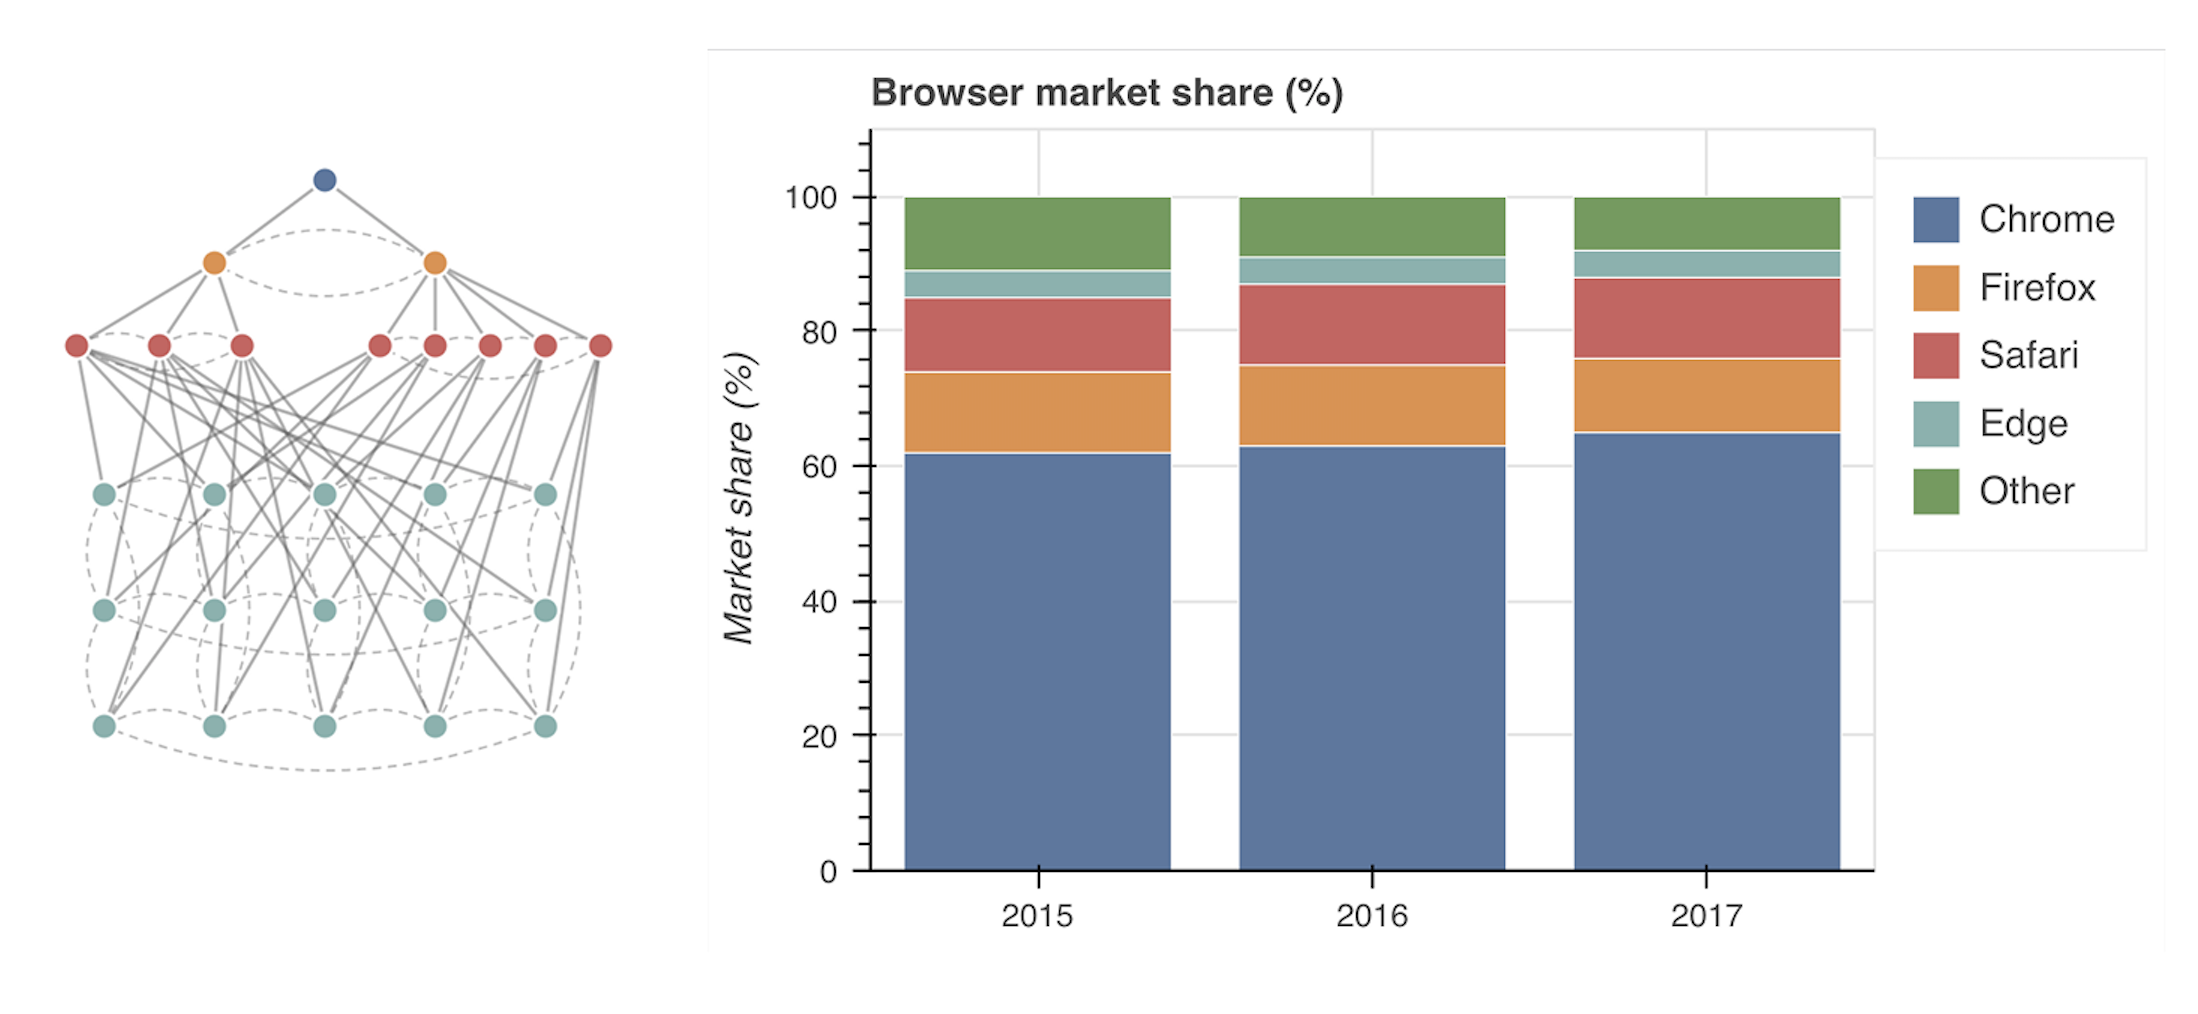
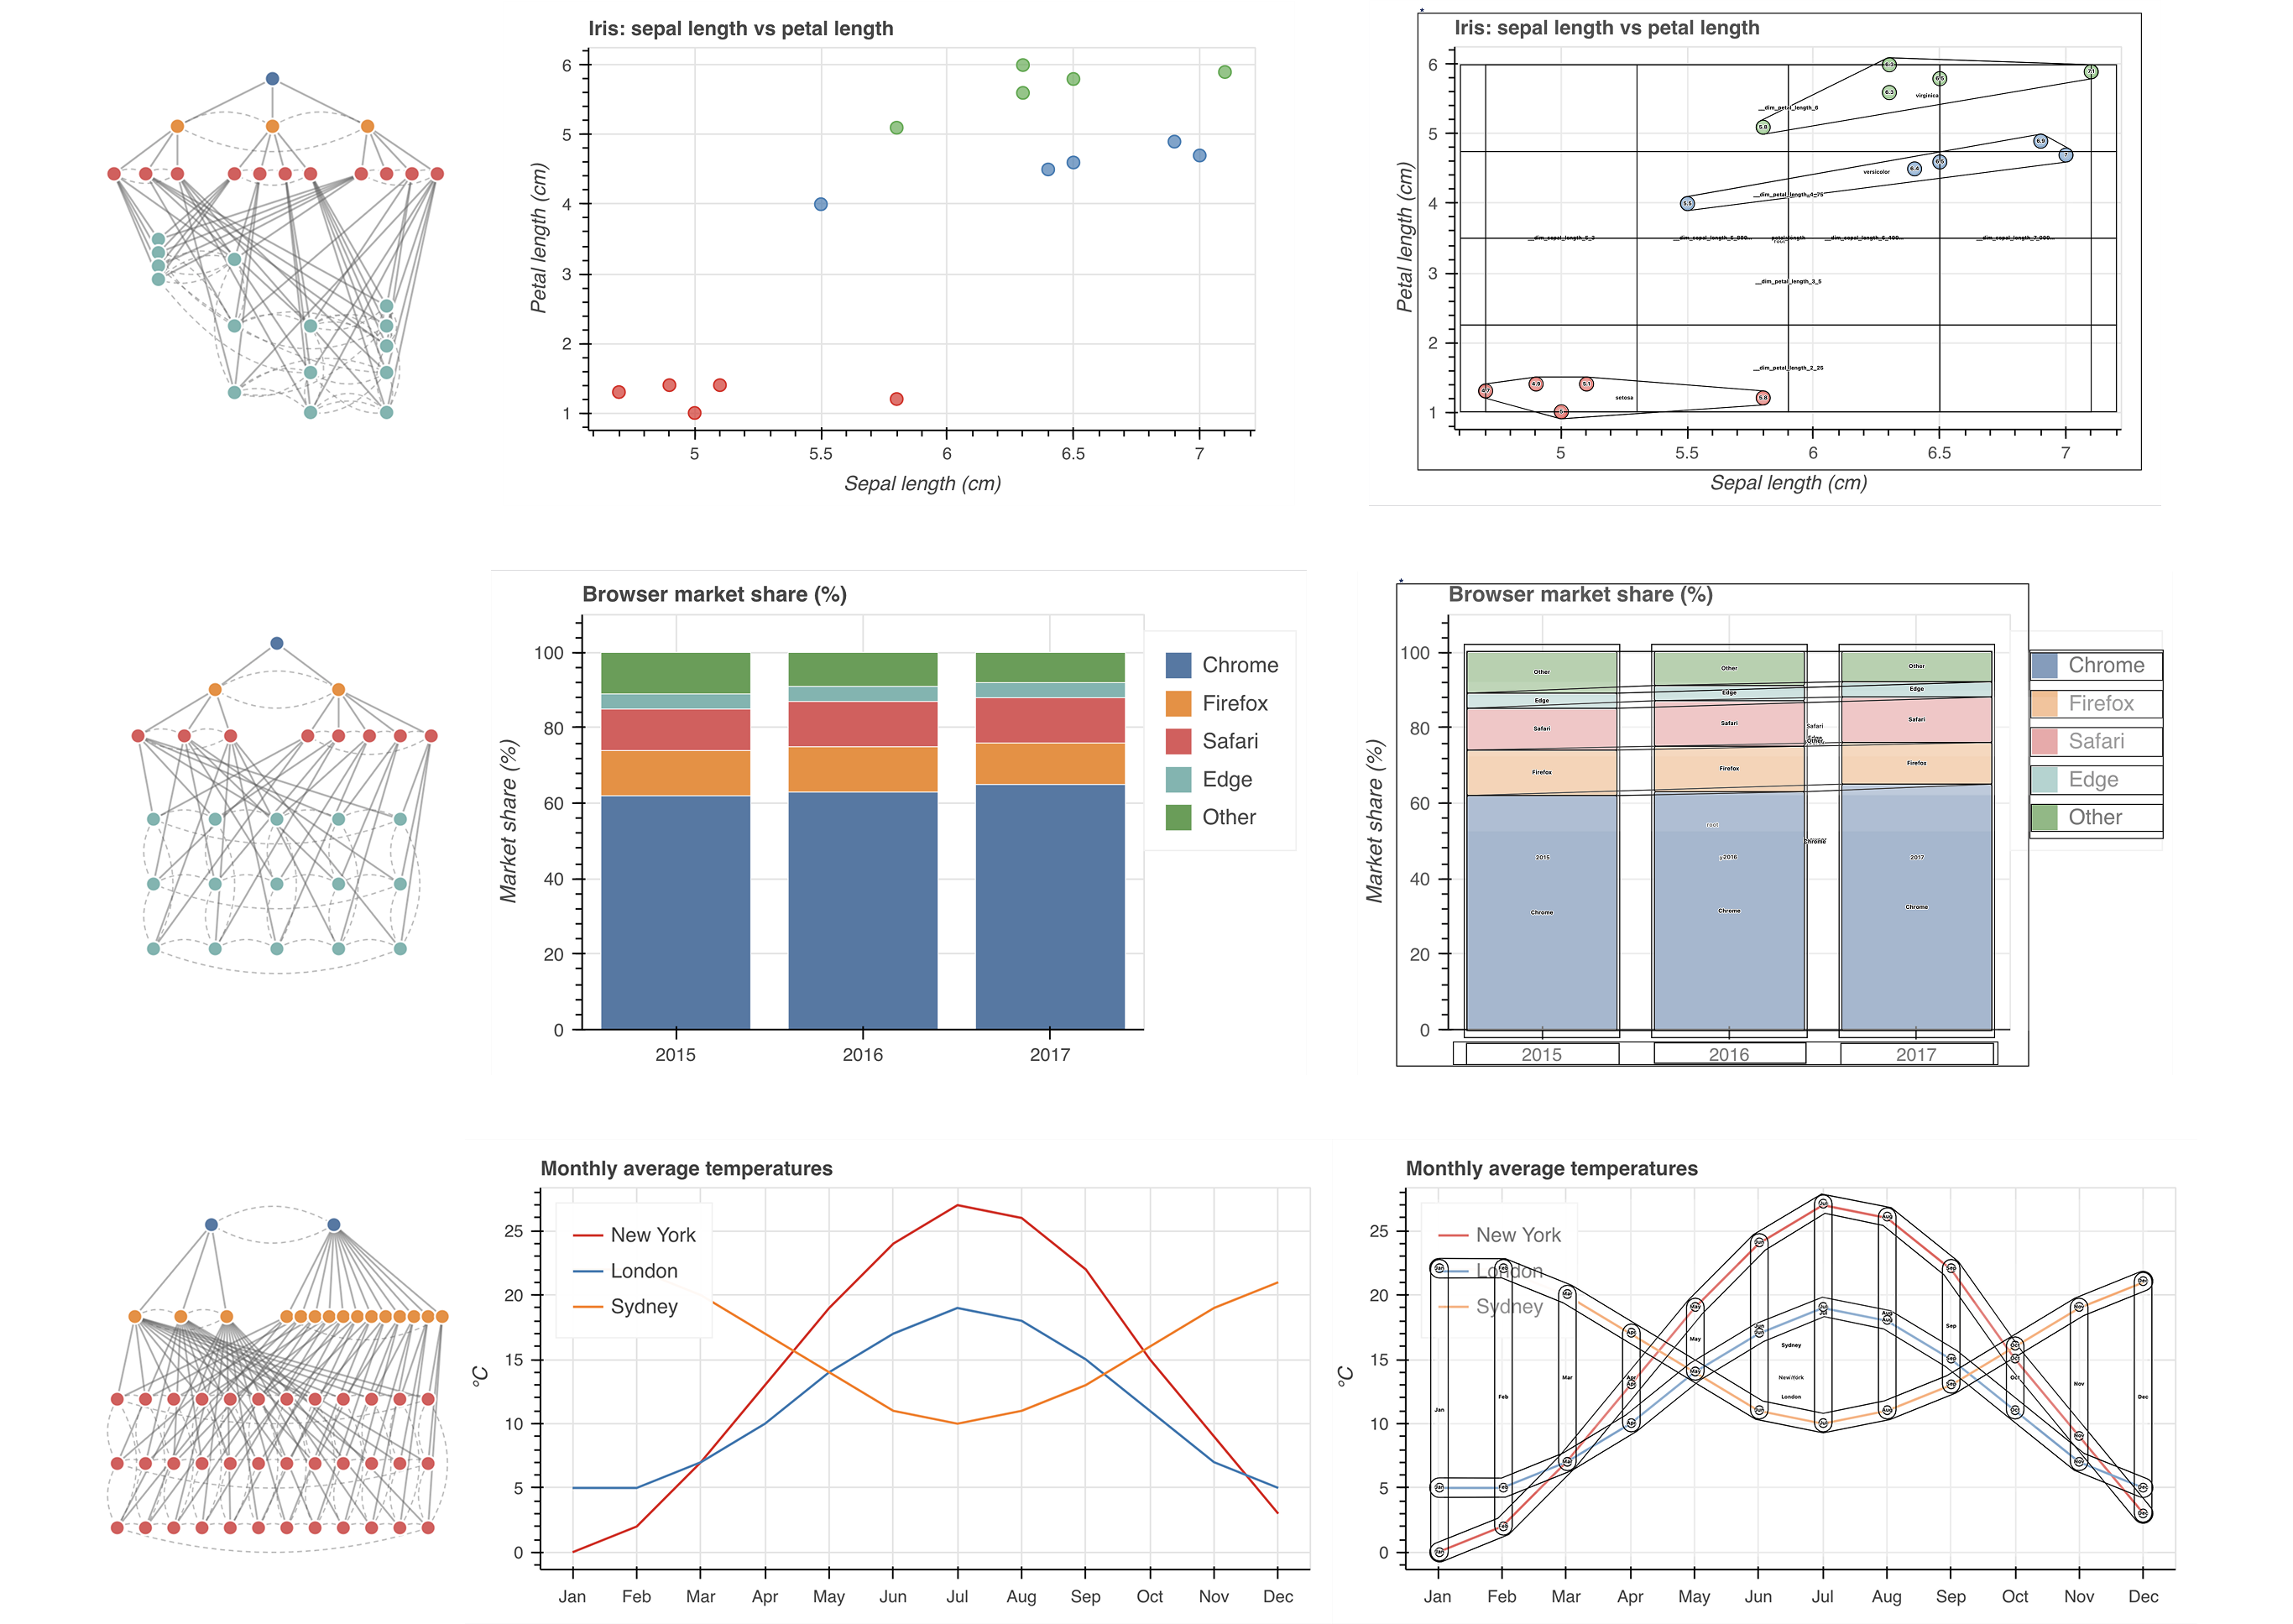
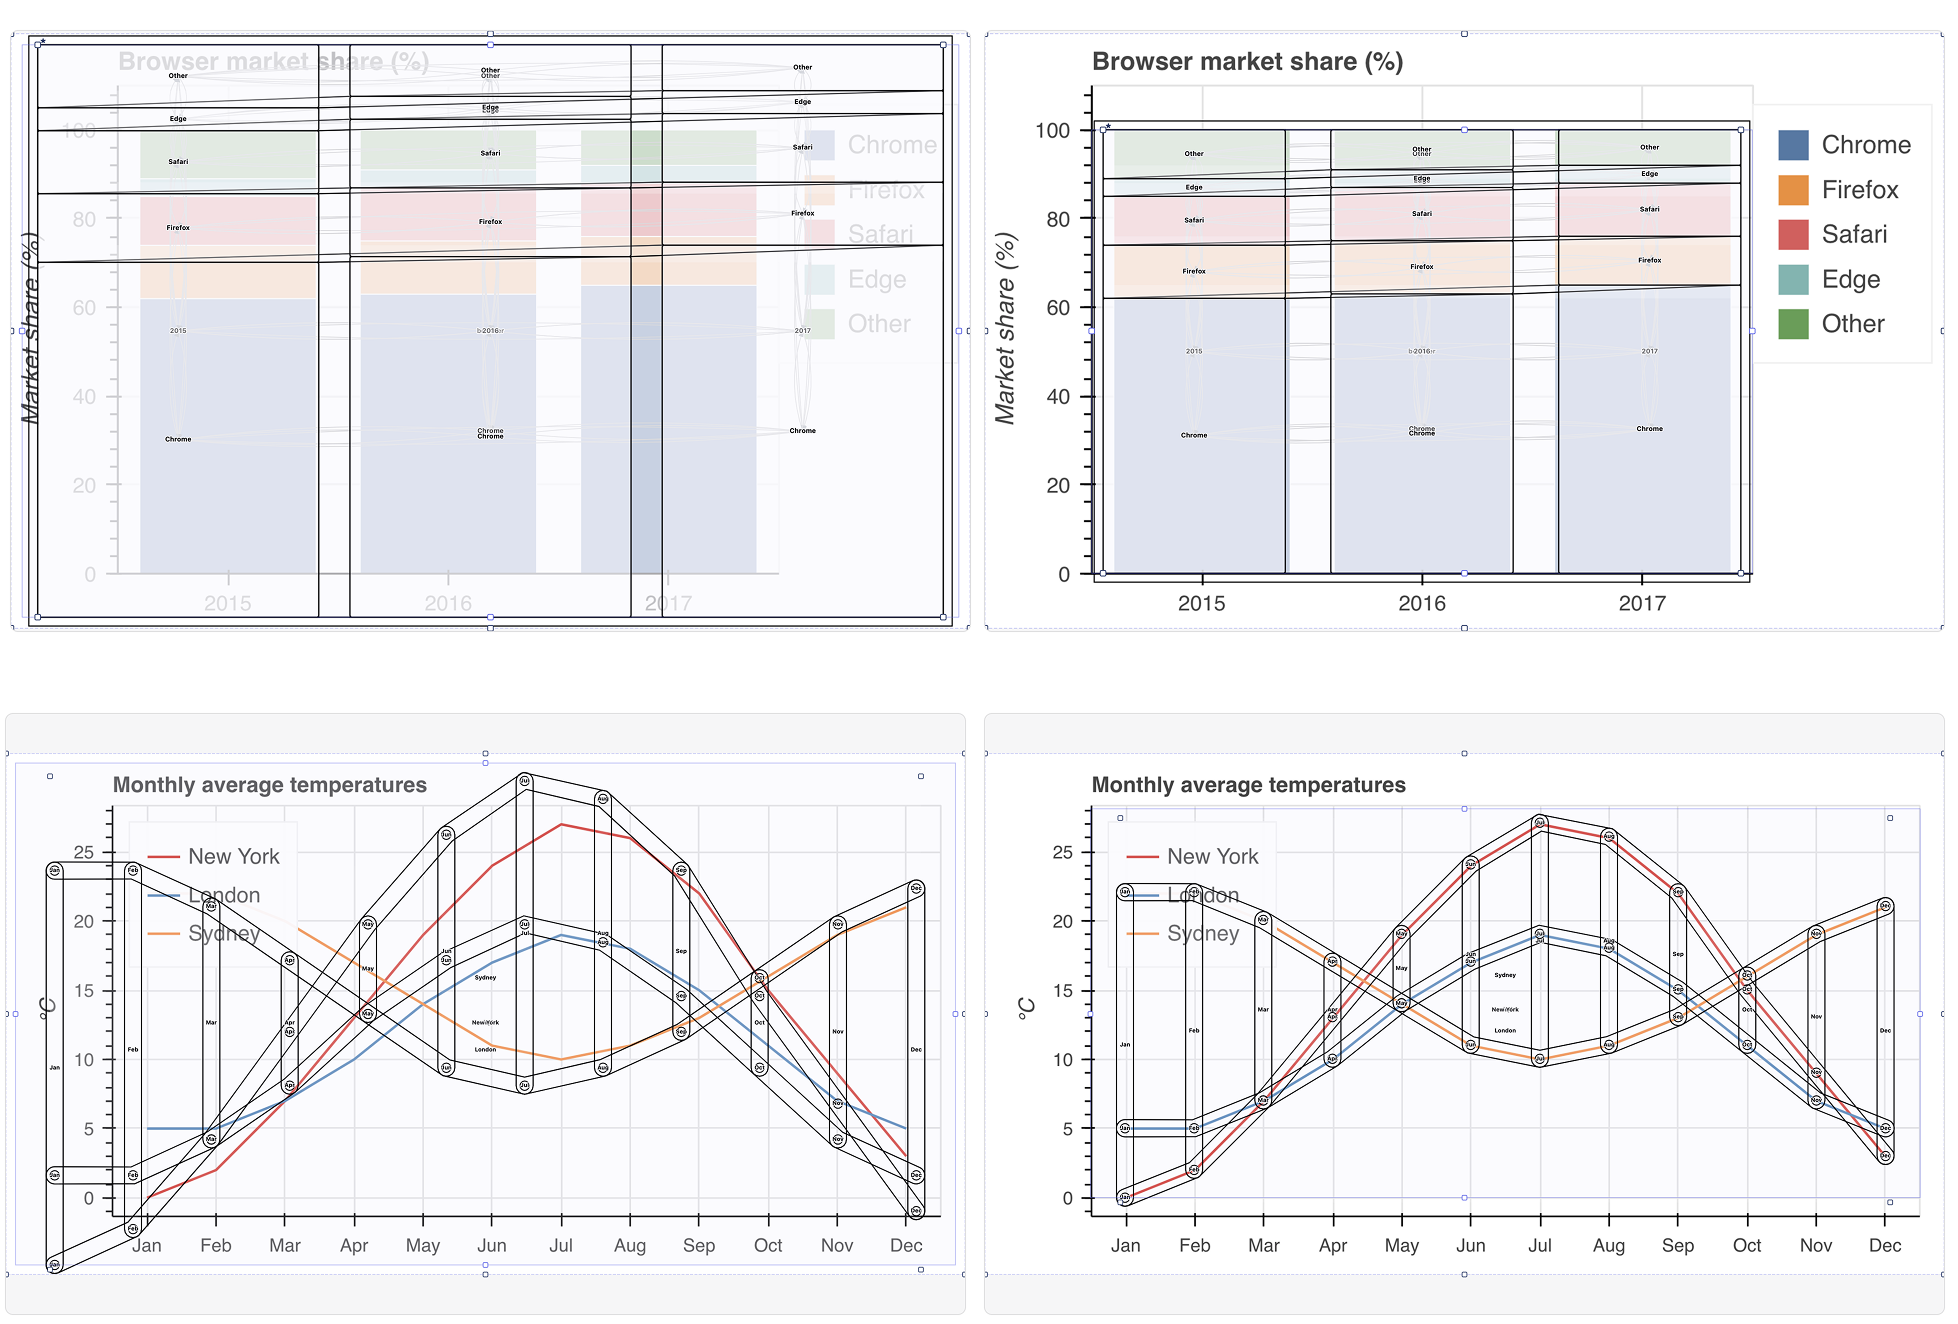
An example structure is visualized using our inspector (on the left) created for a stacked bar chart (on the right).
Introducing: Our alternative “Dimensions”
Our “inspector” gadget is a play on Inspector Gadget, of course. And “alternative dimensions” here is a play on alternative text, the encoding dimensions used in a grammar of graphics (that then correspond to X or Y axes, colors, and so on), and, well, alternative dimensions (from science fiction and the sort). But our tool is called the “dimensions API” and this came about out of necessity, much like our inspector did.
With data navigator, our primary tool for building navigation experiences, we found out relatively quickly across our own work as well as our co-design work that several “patterns” began to emerge as the dominant choices for treating different types of charts and encodings.
With Olli and Zong et al’s work on “Rich Screen Reader Experiences”, they came up with a multi-tree solution for navigating charts and empirically demonstrated that it was useful. In data navigator (our paper portion of the project, at least), we came up with a pattern where children nodes could share parents (or rather, be the leaves of multiple trees at once).
Yet, data navigator’s example patterns were wired up “by hand” in the sense that every data point had a node (or derived nodes) and edges produced manually, by typing everything out in a long and frankly complex specification. Data navigator simply uses a graph under the hood, which is cool and useful, but when it comes to charts and graphs (which often have common structures), this naturally led us to building a higher level API that enabled us to rapidly build useful structures, and especially ones with a structural correspondence to common types of visualizations.
We have a whole walkthrough article written on how the dimensions API works that is worth exploring, in our Data Navigator docs. Also, all of our examples in our “Bokeh Wrapper” (a project we did that didn’t get discussed in the paper) leverage the Dimensions API and also show some of these higher-level patterns for navigation across different chart types.
In brief: the dimensions API enabled us to automatically scaffold navigation experiences based on commonly known inputs that are shared with charting libraries and grammars of graphics. This meant that we could then integrate data navigator into visualization libaries at a low level. Neat! (This enabled our work with the Adobe folks, for example.)
What is missing, though? This seems great!
Well, our Adobe folks are about to solve their design system chart components and we built a wrapper for Bokeh’s visualization library… so what is the problem? Isn’t the work now done?
No, of course not!
The gap that our collaborations helped us to really understand is that authoring (in code) still remains entirely non-visual. We wanted to explore what it would be like to have tooling custom-built for making it as easy as possible to design, iterate, build, test, and iterate again. We built that tool (it is what we call “Skeleton”).
Introducing: Skeleton 🩻
You can find a live, interactive version of Skeleton at this link. We have “save” files for skeleton, too (if you want to load it at a specific view, to see the magic happen more easily than slogging through the wizard for a few minutes). You can access these from Step 0 (upload) and choosing “Load an example.” We have unprepped options (will require using the wizard) but also ready-to-go options that take you to the editor (and let you click the “scaffold” button to see the magic happen) or go straight to testing and poking around with a keyboard or text commands.
Note that this is a research prototype that we built entirely so that we could test our ideas and run a user study. So don’t take the tool too seriously as a production-ready tool. (It isn’t.) Instead, view it as an exploration of our core question and following ideas in one place.
The core question we have centers on: “What happens if sighted designers and developers can author, design, and debug non-visual navigation structures using direct manipulation of visual representations?” (Our paper breaks this question into two separate research questions, but the aggregate combo of them is this, roughly speaking.) And in order to support this core question, our UI was built around the following ideas:
Idea 1: What if you could visually manipulate and author navigation structures?
Put simply: what if you could create something like what our inspector view shows, but entirely in a visual way? Right now, nodes and edges are created using code, then shown in our inspector. And yet, this code is often attempting to re-create a visual design specification. The workflow is: Navigation designed visually -> handoff to developers -> Developers code. But what if we cut out the middle, translational step? What if the same activities we take during the designerly phase (creating markers for navigation locations and drawing paths for navigation) automatically scaffolded the structures that Data Navigator requires? What if you could add, delete, and move around nodes and edges freely by directly manipulating these elements?
So, we built that. We call this view the “editor” in Skeleton.
Idea 2: What if you could auto-magically scaffold the visual part of a structure for most common chart types?
Put simply: the inspector is what the system sees. But we also want to see another visualization: what the end user will see. And yes, many people who use navigational assistive technologies have sight! (We talk about this in our Data Navigator paper as well as demonstrate it in our section on “trouble with focus indication” in our docs.)
Note: see the figure in the section below on Idea 3 to get a better sense of what the heck a focus indicator or visual outline even means.
But navigating directly over a chart space according to the visual elements and arrangements in that space is what Mei and Pollock call “visual congruence” [1]. Having visual congruence is an important part of making the visual part of a visualization (and not just the underlying data or structure) accessible, too.
Imagine trying to navigate something you see, but you don’t know where your current “location” is. That’s the problem! We need to show users their visual location as they navigate.
This is the hardest part about building non-visual navigation structures (from a technical perspective, not necessarily a design perspective). Knowing where nodes are actually shown visually when a user navigates to one is quite difficult to figure out how to make happen. If a visualization is rendered using pixels… we don’t have access to the location data while someone navigates. Some visualization engines, like Bokeh’s, don’t expose this information. This means that our wrapper for Bokeh actually has to place the real focus over the whole chart, even though we then provide a fake internal focus within the chart (not ideal, especially for users who have a high level of zoom and are viewing a large-format chart).
There are a few scenarios we can engage this (organized by most-difficult to solve to easiest):
Scenario A: Sighted end user has a pixel image and wants navigation added
The hardest scenario to solve for would be an end user who has some sight or partial sight, but still uses a navigational tech. We can’t get element location info let alone data information. Chart extraction methods have attempted for years to pull data out of a rendered chart, but depending on the method and circumstances, the results are prone to error. For example, if a scatterplot has overplotting, then significant data is lost. Not ideal. But computer vision could at least help find locations and reverse-engineer the element locations and data values.
Scenario B: Completely blind end user has a pixel image and wants navigation added
In this scenario, we don’t need to place elements in any particular spot visually so long as the structure is correct for them to navigate. This unfortunately still has the same problem as before in cases of overplotting, as it still requires chart-data extraction methods. Not ideal, either but not quite as hard.
Scenario C: Dev user has access to the data, sends it to a visualization library to render pixels
In this scenario, now we are cooking. Rather than placing the burden on the end user (and likely creating an unsolvable or unideal experience), we can go one level up to the authoring process: the moment that a developer passes a dataset (and some kind of specifications) to a charting library, visualization tool, or grammar.
The user might be a journalist making a chart using a tool, a business analyst building a report using excel, a web developer who is leveraging a canvas-based tool like Bokeh, and so on. The “user” here isn’t an end user, but a developer- or designer-user. They have a dataset and a charting tool. And at this intersection, we can solve quite a lot of problems! (We unpack this below, because it is the hardest-to-solve scenario that we believe we can solve. But we will still outline other scenarios, those that are more ideal than this one.)
Scenario D: Dev user has access to the data, sends it to a visualization library to render SVG
If we have SVG? we can reasonably extract the locations of rendered elements. This isn’t easy, per se, but relatively speaking this is trivial to solve for now.
Scenario E: Tool-maker is building a charting library or tool
In scenario E, we can also easily solve our problems. In the context of building your own charting library (like we did at Visa via Visa Chart Components or in our collaboration with the folks at Adobe building React Spectrum Charts), the library itself has access to its own rendering engine. That’s the point of the library, after all! And if you can hook into the lifecycle of drawing things, then you can figure out where those things are when it comes time for a user to navigate (even if those things are rendered in a pixel-only format).
The “Scaffolding” tool (and solving for Scenario C)
(Recap on this scenario: So a developer is using a tool that creates pixel-based visuals for them, say Bokeh or Excel or something. The user has their own dataset, which they use as input for their tool. After rendering, they want to make a navigation experience for users of assistive technologies.)
This scenario has input data and input specification (aka chart type or encodings) from our user. We believe that this is enough to automatically add visual congruence to a navigation experience!
This is where we had some fun ideas. Why not use another charting library to gain access to element location (by effectively replicating the user’s own visualization)? We can throw away the visualization we replicate after getting the location information we need, too. So this is just a temporary, deterministic calculation step. Visualizations all use the same fundamental math to translate a domain into a range. D3’s whole “scales” ecosystem exposes this. So, what if we just re-render a chart that mirrors the one the user started with? We did this, and it works beautifully (with one single caveat, below.)
For our “scaffolding engine” (as we call it), we used Vega. Vega exposes element location in their view model. We conjectured: what if we take input data from our users, get info about what type of visualization is rendered (or encodings used), and then not only can we automatically build a navigable structure but we could also automatically scaffold the locations of the elements in that structure!
Using our scaffold tool with 3 different charts. Left: the structure from our Inspector (what Data Navigator "sees"). Middle, the input chart (just made of pixels). And right, visual indicators placed over each element (all indicators are shown at once).
Now, scaffolding isn’t actually all fun and games. We do a little bit of dark magic in order to get these outlines to fit properly. Namely, we really only used our scaffolding engine to extract mark locations, group information, and so on. We also need to solve for two other things, first: how to outline different groups of marks. And also: how to figure out exactly where the mark space is rendered. Visualization tools employ a lot of different opinions about how to pad around the mark area. Axis labels need to be considered, as well as other things like a legend, generic padding, subtitles, captions, and so on. We can’t assume that the cartesian coordinates for 0,0 on our mark space is relative to the 0,0 absolute position on our input chart!
For shapes and outline strategies, we simply built a generic library devoted to different geometric strategies (convex hulls with padding allowable, rect outlines, union of all child outlines, and so on).
For finding the padding, we do a little heuristic based (non-ml) computer vision pass, to estimate where the mark space begins. (For details about how we did this, simply see the appendix of our paper or our open source code for skeleton.)
Automatically computing visual congruence. First, computed layout for marks via Vega’s visualization engine plus group outlines (left) and then with with padding estimation using our non-ML computer vision approach (right) for various types of common visualizations. Average time to compute all outlines is 250ms (one time cost, up front).
Idea 3: What if you could test navigation without even using specialized tech, like a screen reader?
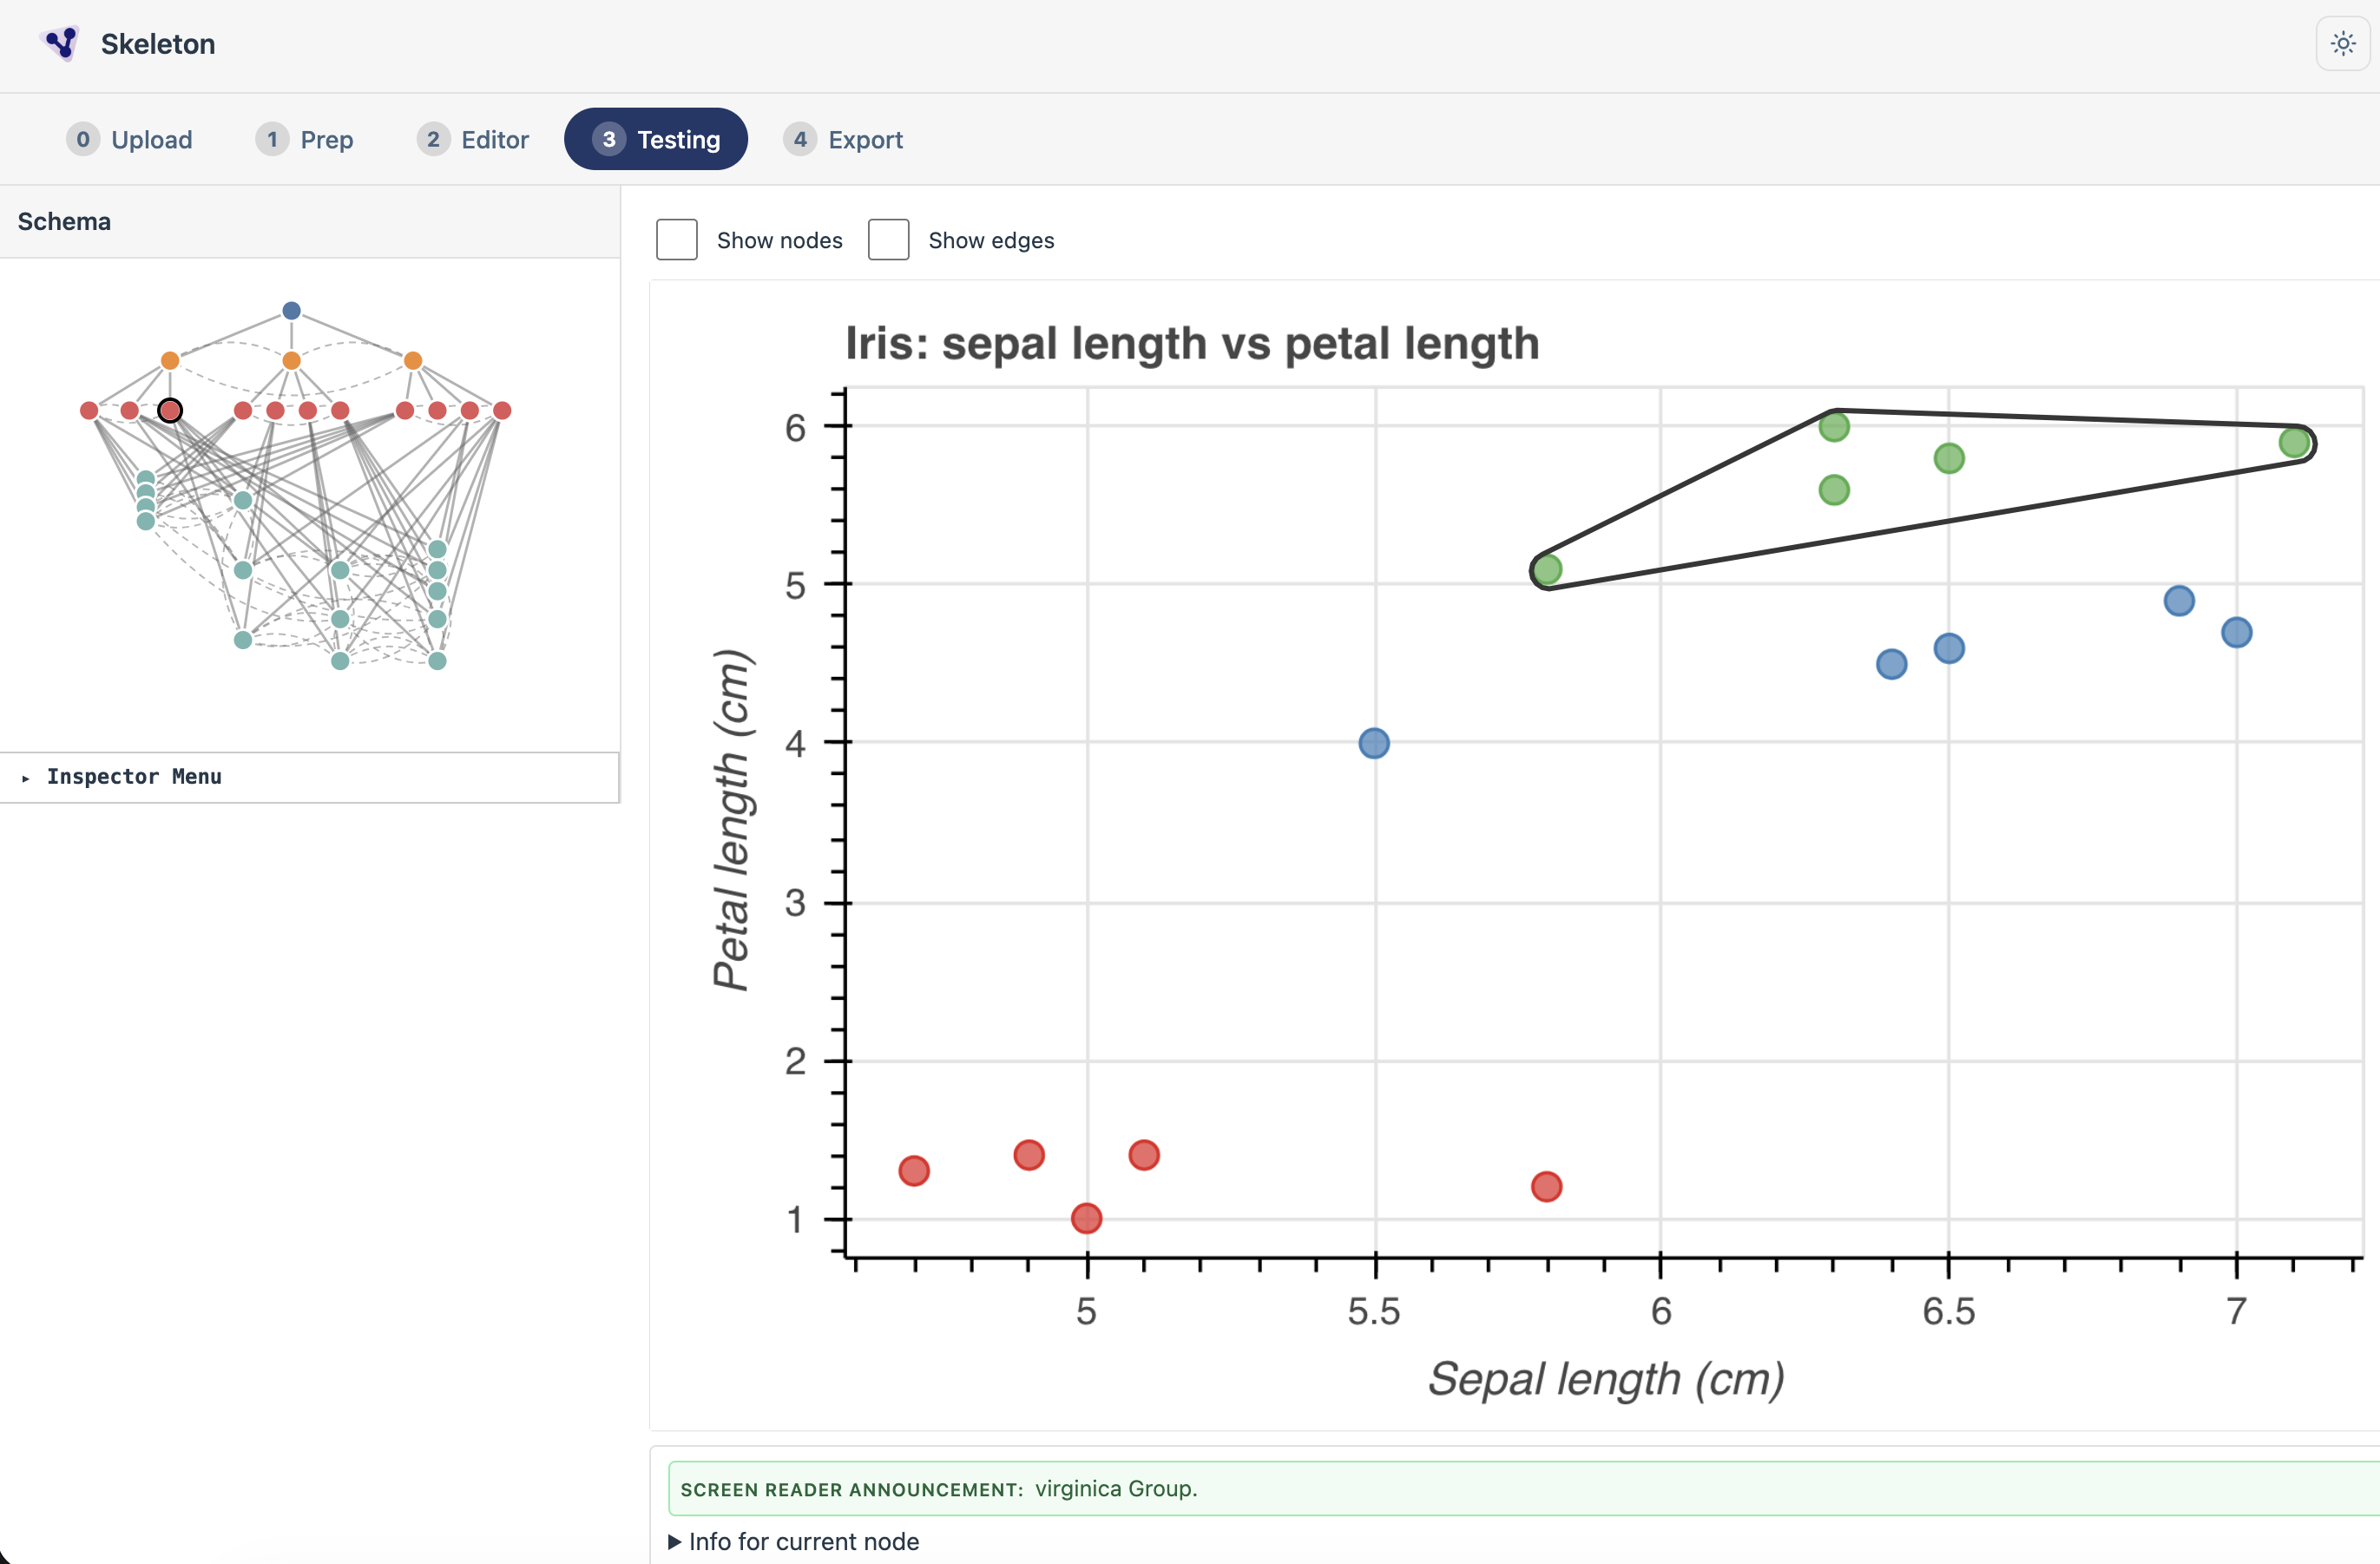
Lastly, we wanted people to be able to immediately test their designs both functionally (does navigation operate as expected? do the correct relationships exist?) as well as visually (are elements in the correct location? are groups outlined in a reasonable way?) and non-visually (do the labels that are generated for a screen reader user make sense? can someone figure out how to explore this non-visually using our text and alt text alone?). And this became our testing page! No screen reader required. This page replicates chat based navigation (typing commands), keyboard nav, as well as screen reader nav (complete with visual previews of the otherwise-hidden alt text for each element).
Our testing page. A visual focus indicator is shown over the chart space during navigation (center view) as well as where that node corresponds in the overall structure (shown as another focus indicator in the inspector, in the upper left). We also show screen reader labels as they would be read by a screen reader at the bottom of the testing view.
Our study and findings
Honestly, you should read the paper for all the juicy details of our study. It was a blast. The study design was simple: we used our prototype for Skeleton as a “design probe” to surface qualitative insights about how people orient and reorient their work while trying to make visualizations accessible. We had users do a “test run” of the tool, where they tried to make a visualization accessible (and we intentionally included a bug fo them to possibly find). After the test run, we asked them to bring an image of a visualization they are currently or have recently worked on. At the end, we had an interview where we asked some semi-structured questions. All of our participants were visualization practitioners in some role (as engineers, designers, data scientists, or researchers).
Since Skeleton became the final proposed project in my thesis, I also pontificate/reflect a bit on the chapter (chapter 6) in the thesis as well. My biggest takeaways are:
An improperly designed system can produce barriers for anyone, even people who are sighted. This means that sighted people need barriers removed and yes, even people without disabilities require our world to be accessible. “Accessibility is for everyone” has long been understood as this idea that everyone experiences situational limitations or temporary disability (or we all age into disability if we grow old enough). But in our paper, it is clear that “Accessibility is for everyone” also means that poorly designed software or a user who is trying to do work in a modality that is unfamiliar to them will require accessibility too.
Making non-visual elements visual and directly manipulable shaped how sighted practitioners thought about the design problems. They stopped thinking as much about compliance or what was “required” and began to recognize that navigation is its own space of design consideration.
Making non-visual elements visual, such as text read out to screen readers, led sighted practitioners to heavily iterate (independently! they were not asked to do this). They went back and forth, clearly thinking through the ideal, low-level details of a blind user’s experience navigating a data structure.
Making non-visual elements visual, such as the paths and elements of a navigable structure, led sighted practitioners to heavily iterate and even reconsider their visual designs (their own charts and graphs), because they recognized the relationship between their visual design choices and the non-visual experiences that users would have.
Making non-visual elements visual and directly manipulable actually influenced one practitioner to decide that navigation was a poor design choice for the specific, bespoke chart they had brought. They decided that navigation didn’t make sense for their chart and instead opted for non-design. (Really cool and surprising choice!)
Ultimately, sighted practitioners think and reason about design in visual ways. And by making non-visual elements legible and interactive, we saw them re-prioritize and reconsider the design of non-visual user experiences. A step in a very interesting direction for future work and future accessibility tools!
What’s next?
Well, Skeleton the idea has been thoroughly tested. But Skeleton the prototype user interface has significant hurdles to overcome before it is really ready for public use. It is full of bugs and assumptions, the code is poorly optimized, and t lacks one of the most important features that will determine its success: exporting what you build with it. Right now, Skeleton let’s you import, prep, edit, and test. But you can’t export, so it is only useful as a design tool. Once we lock in on exporting functionality and build it out, it’ll become far more useful for most designers and developers. More to come!
]]>Final thesis complete and the three versions of ‘PhDone’2026-07-12T00:00:00+00:002026-07-12T00:00:00+00:00https://www.frank.computer/blog/2026/07/three-phdonesWell, it’s official: my thesis is finally accepted, published, and done. And this marks now my second of three milestones having been met for the PhD.
If you happen upon this blog post and haven’t seen my other one on, “Who actually reads a PhD dissertation?” I also generate a bunch of versions of my thesis that are smaller and focused on certain audiences. It’s a good read and a fun chance to see how I chopped my thesis up for easier reading. Perhaps this will catch on?
But this short post will outline the three ways that a PhD is considered “complete” and moments where a person can consider themselves a PhD in something, officially or unofficially. I organize these three as: The Social, The Official, and the Ritual methods for being considered a PhD.
On The Social
When a PhD candidate is prepping for their dissertation, it is common to propose your thesis (which is often done as a talk) and then, after some time, the thesis is defended (also as a talk). The candidate is socially considered a PhD once they pass their defense.
For me, I had to defend my thesis publicly (which I invited folks to). I had many in attendance (maybe 100? more?). But often, a thesis defense is attended by just a small handful of people, plus the thesis committee (who are often on offense).
Passing the defense tends to result in folks announcing on social media, calling their mom, hosting a bbq, and so on. This is the moment that the rest of society sees a person as having achieved a PhD.
On the Official
But technically, a PhD is awarded by an institution. And this means that there is paperwork. And sometimes, like with me, I had some more work to do on my thesis before submitting it for institutional go ahead. This moment tends to be lackluster and unexciting, but it is when the actual PhD is awarded and the thesis document is published somewhere in an archival format.
Sometimes, this happens the same day as the defense. But in other cases, there have been stories I’ve heard where the official stuff took years. Sometimes people can even get jobs after their PhD “ends” and they are still working on their thesis document.
But at CMU and the HCII, I had the privilege to stay on stipend and get paid all the way up until the absolute final moments (when I need to start processing my paperwork for my next job as a professor at Cal Poly). So for us, I had the chance to polish my thesis, integrate my changes from my conditionally accepted chapter at IEEE VIS, and get a little extra pay for the 2+ months I was hanging around. I love that the day of the defense isn’t closely tied to the day the official paperwork goes through. It’s a great part of the way the system currently works.
The hooding of a PhD is an ancient ritual and is when the PhD’s total journey is considered complete. However, due to the highly variable nature in which PhDs tend to be completed, it is common that a hooding takes place long after the social and official milestones are completed. For me, this will be the case.
I missed the deadline to be included in the PhD ceremonies at CMU by a few weeks (based on my defense) and a few months (based on my official documentation). But in my case, I am incredibly fortunate: CHI (our top research venue) is being hosted by CMU and others in Pittsburgh next year just about a week off from the time that the ceremony takes place. So I’ll be returning in June of 2027 to get my hood.
The hood is a fun part of the process, because you get a color that corresponds to where you got your PhD (mine has the CMU tartan pattern) in addition to a color based on your discipline. The color based on discipline tends to be regionally determined, and in the United States, computer science is a philosophy degree, meaning it is dark blue. Dark blue elsewhere could refer to law or something else.
But once these three milestones are met, there’s generally nothing else major worth noting. You’re PhDone three times out of three.
]]>A selfish manifesto towards rejection of generative AI2026-05-18T00:00:00+00:002026-05-18T00:00:00+00:00https://www.frank.computer/blog/2026/05/selfish-manifestoI’ve heard great arguments for rejecting AI for environmental reasons (water, climate, energy) and for ethical reasons (like the theft of all digitizable intellectual property). I’ve even made those arguments myself (see previously linked blog post).
But I also want to suggest another angle that can be used in conjunction with these: rejecting genAI for selfish reasons.
For context, it is nearly the 1-year anniversary from when I authored my blog post on “Stop saying that AI is just a tool and it only matters how it is used”. It is easily the most successful blog post I’ve written and certainly gets more impressions than my research papers 😂. But I love it especially because it helped me form my own thoughts at a time when I felt like I was losing control of things (research budgets getting cut, anti-immigration on the rise, the impending deadline of my thesis work, future job insecurity, AI companies consolidating power across the world, facing irreversible climate disasters in my lifetime and so on).
Here is my small, humble manifesto for rejecting generative AI on selfish terms.
1. Defending your own friction, your own struggle
Hayao Miyazaki said it best, “if life’s hassles disappeared, you’d want them back.”
But this is a meta-point, which the former blog itself makes: that struggling through writing is a miraculous task. And by doing it myself and not offloading my thoughts to a machine, I gained a new piece of myself that I appreciate. At a time when so much is out of my control, the ability to congeal a messy space of thinking into a structured set of thoughts brought a little order into the chaos of my life.
And writing isn’t just a “mirror” into your own thoughts. It is a vehicle for developing the skill of thinking and reasoning. It’s both a reflective and generative practice. You create thoughts through writing, not just invoke what is already in your brain. If more people who prompt their way through life realized this, we’d be taking back the frontiers of labor in our inner minds from AI companies.
2. Holding precious your own thought-making
“What are you trying to be free of? The living? The miraculous task of it?” - Joseph Fasano
I don’t care if a machine can think better than me. My thoughts are precious and being able to form them through writing and socializing with others currently has no equal practice. Prompting appears to give the benefits of both the writing and socializing at once, but it actually steals the benefits of doing both of these acts from us. This is because the part of these activities that matter, the friction that exists in writing and socializing, become the selling point of AI: it’s frictionless.
Anyway, best of luck to all of us as we navigate the new world we live in. We all now need to figure out which portion of our minds are worth delegating to machines on our behalf. What bits of difficulty do we want to keep in our lives, and what does it do for our sense of self?
One question I hold myself to is: if I wasn’t being paid to use my brain, would I still want to? And which things do I still enjoy thinking about?
Hullman writes that the enthusiastic pro-AI discourse strikes her as “nihilism masquerading as optimism.” And so it is worth asking ourselves: what part of our work should remain fundamentally human?
3. Focusing on your own need for joy and responsibility
Focusing less on tasks I can complete and the time it takes me, and more on what gives me joy to think about (even if it is hard) has been central to me. Secondary to this has been my sense of moral responsibility. Turns out, I value writing immensely. This means that generating code, a blog post, a poem, a work of fiction, a text to my wife, or even emails to coworkers are all things I’d rather do myself and have a sense of sole responsibility over.
I enjoy deterministic systems, for example. These give me a sense of self-interpretation. I can question my own thoughts when a deterministic machine fails: did I fail to construct language in the right way? Do I have assumptions about the problem or solution? But when interacting with a non-deterministic machine, like generative AI, instead I tend to focus on the machine’s own failure and randomness. I don’t gain a sense of absolute clarity in my own mind, just a fuzzy closeness that exists somewhere between my thoughts and an agent’s performance. I cannot imagine someone else holding me responsible for this fuzzy space, this broken and un-inspectable space. I enjoy sleeping at night knowing that I can be held accountable for the things I’ve chosen to do. But the things I’ve chosen to delegate or manage? Perhaps those things failed because of my agent, “co-worker,” or minion-machine.
Perhaps we should start asking ourselves: what difficulty brings us joy, and what work do we want to remain responsible for?
]]>Who actually reads a PhD dissertation?2026-04-20T00:00:00+00:002026-04-20T00:00:00+00:00https://www.frank.computer/blog/2026/04/who-reads-dissertations
[EDIT: 07/2026] This blog post was originally written when I first submitted my thesis for review with my committee, prior to my defense. But now, the final draft is available. All of the links below have been updated to point to the newest version of each doc (you may need to hard-refresh the page to get the newest version, in case the old one is stored in your browser cache). I am very happy with the latest draft - it is a significant improvement over the original, which was mostly a staple-job thesis in the purest sense (this now really expands several chapters and also adds a preface and postface reflection to each). I’ve also added a real, proper conclusion section as well. Exciting! Hope you enjoy and thanks to those of you who read the earlier draft and gave feedback. I really appreciate it.
Also note: the main thesis doc (linked here) is tagged for accessibility. The others are auto-generated in python, so their accessibility is limited. Apologies for the technical limitations! And for anyone else interested, my code for generating the subdocs for my thesis can be found here.
Well, howdy! This blog post is mostly just a fun adventure/experiment where I try to make it easier to read and engage with academic work, simply by altering the format.
This core idea was already the focus on my micro-paper project, where I mused: is there a place for 1-2 page micro-papers in our larger academic conversation? I am conjecturing that smaller pieces of an idea, or smaller units of information, might get broader or qualitatively different engagement than longer-form, archival, written media.
And the opening question of this blog post: “who actually reads a PhD dissertation?” is largely answered with, “nobody except the committee.”
But even so… committee members don’t often even need to read the whole dissertation itself. For mine, this document (24 pages) is really what my committee needs to focus the most on. They’ve all probably already read or are familiar with my main research projects. What they care about is how it all comes together (so basically the beginning and end parts of the document).
So if committee members aren’t reading the whole thing and basically nobody else does (because these things are sometimes 200 pages long), then what the heck is the point of a thesis? The point, of course, is to have an archival-quality record of the work and the defense made by the PhD candidate. The primary purpose of publishing a dissertation is just to show to the world that the work was done.
Yet, I reckon that many different parts of the thesis are actually valuable and interesting to folks who aren’t academics or who are but are unfamiliar with my body of work. I have been stewing on a paper by Mohammadi et al, “Who reads
research articles?” and it turns out that all kinds of people do. So then I wondered… is there a way to make my thesis more-digestible for different kinds of folks?
That led me to the following: What if I could generate a bunch of smaller docs from my thesis, based on assumptions I have about different kinds of readers? Would this simple change of format make my thesis more accessible and more usable? (It’s important for me to think about accessibility, after all!)
So what is my dissertation and what is it actually about?
My thesis is titled, Tool-making as an intervention on the accessibility of interactive data experiences. I specifically study how tool-making is a site for generating knowledge about how people engage with difficult practical problems. I make tools and then use those tools as a probe to understand more about authors, creators, and users of data experiences.
My core argument (the “thesis statement” at the heart of the dissertation) is this: “This dissertation argues that the tools practitioners use to build interactive data experiences are themselves sites where accessibility barriers are produced, prevented, or alleviated for both end users and authors. This work contributes fve tools, Chartability, Data Navigator, Skeleton, Cross-perception, and Softerware, that collectively center accessibility work on the empowerment of disabled and non-disabled practitioners across the full arc of evaluation, data navigation, analytical interaction, and personalization.”
My work is interesting primarily because I argue that the work practitioners do is a rich site for research. I don’t just make a proverbial “hammer” but study what sort of hammers we need, whether hammers really work, and then how people actually use them. (You can find the whole thesis here.)
Well, perhaps my dissertation has piqued your interest a little? And perhaps you don’t know where to start? Well look below, and perhaps one of these categories applies to you and your interests or experiences.
(Below is a series of sections/subsections taken from a previous blog post announcing my thesis defense, which of course you are welcome to attend at noon EDT on April 29th, 2026. So, please feel free to see if any of the documents are actually interesting/useful to you, especially if you fit one of the descriptions of my assumed readership below:)
Should you read my dissertation?
I highly doubt it! But that being said, there are some pretty fun parts in it, worth a skim (depending on who you are). For the most part, my dissertation is a “stapled paper” type of thesis, where the bulk of the document is comprised of my top-papers (that are the projects I personally led and executed) inserted without editing as the main “body” chapters of the dissertation. Then, the thesis itself generally has (up front) an acknowledgements section, introduction, overview of contributions, and (at the end) some kind of summary/discussion as well as a biographical sketch.
🤓 📚➟📖
I’ve generated miniature versions of my thesis document, to make reading easier! The basic document has 180 pages of content (248 pages total). That’s a lot! But I wondered… would more people actually look at my thesis if the page count wasn’t so intimidating? (See below sections for these mini-docs.)
That being said, many folks may want to check out one or some of the sections in the dissertation without having to read all of it. So here are some suggested readings for folks I know who are of different kinds:
Anyone who attends my thesis defense should probably check out my acknowledgements section. You’re probably in there! If you aren’t but think you should be, let me know!! I am terribly forgetful and would hate to leave out a friend, colleague, or supporter.
It also might be worth it to skim my biographical sketch, especially because the introduction to it pokes fun at many other bio sketches where people love to point out their origins as a genius child in high school who then ascended to harvard/MIT/etc; brilliant because of their own individual genius, of course. By contrast, I have largely been an unremarkable and unaccomplished person. I was a terrible student in high school and mostly didn’t “deserve” or earn the opportunities I had in life. And yet I did remarkable things regardless, mostly thanks to all the folks who have helped me out over the years. I hope my biography is a testament to the power of social support and that I have never really been a “main character” in my life. (Note that my own advisor joked that he wished he had paid more attention to my PhD application, because my undergraduate closed and I did poorly in high school. I probably shouldn’t have been admitted to CMU, haha. He is certainly from a “real” academic and technical pedigree; he would know!)
2. You are a technical practitioner of some kind (non-researcher)
I’d recommend that anyone technical (whether a designer or developer) checks out 1.2, 9.1, and 9.3. Pretty much everyone who works with “tools” (including AI/genAI/LLM/ML tools) should check those out (as well as my blog post on tools.)
You are specifically an accessibility practitioner
Definitely read 1.1 of the introduction because it has a way of thinking about accessibility work that everyone doing any accessibility work should consider: is “accessible visualization” really an oxymoron?
I think that academic papers can be awkward to suggest, but I genuinely think that if you check out any main chapter, you should read the one on skeleton, since it is about making accessibility work more accessible for sighted practitioners. A lot of accessibility work is (ironically) inaccessible! We should change that. Chartability is another good read along those lines, too.
Absolutely read 1.1 of the introduction: is “accessible visualization” really an oxymoron? I wrote that with visualization folks in mind. There have been some tricky, even subtle ableism in our field that I wanted to clear up before outlining my work. The part where I engage misconceptions about accessibility is worth reflecting on as well as the part where I outline what visualization is actually about.
I think that academic papers can be awkward to suggest, but I genuinely think that if you check out any main chapter, you should read the one on skeleton, since it is about making accessibility work more accessible for sighted practitioners. Chances are: that’s you. I also think that softerware should be a chapter that anyone who builds or designs visualization systems and tools should think about: how do you enable end user personalization?
3. You are an HCI/HAI/visualization/accessibility/”tools” researcher of some kind
All researchers will probably benefit from at least reading chapter 3 (my overview of contributions) and my final section, who is responsible for repair? Read those in addition to any subsection below that applies to you:
I think the introduction (sections 1.1 and 1.2) as well as the conclusion’s sections on what is a tool? (9.1) and applied accessibility research (9.2) are especially valuable, and hopefully provocative. I’ve done a good job if a few people from the ASSETS community are flustered about 9.2, in particular.
You might want to do more practitioner-focused work (or have an interest in this), in which case I’d recommend skeleton, chartability, and softerware especially. Read data-navigator if you want to get mad that I didn’t run a user study to validate our system (challenge mode: think about whether this kind of work is valuable or not in/for accessibility research as a broader discussion).
Absolutely read 1.1 of the introduction: is “accessible visualization” really an oxymoron? I wrote that with visualization folks in mind. There have been some tricky, even subtle ableism in our field that I wanted to clear up before outlining my work. The part where I engage misconceptions about accessibility is worth reflecting on as well as the part where I outline what visualization is actually about.
But “visualization researcher” is a funny categorization to me. Visualization research has cognitive and perceptual scientists (our “real” science-doers), feminist and critical theorists, ethicists, interaction designers, system-builders, graphic designers, data people, and applied researchers. My thesis is mostly written from the perspective of system-building and a little bit of interaction design.
If you’re into cognitive and perceptual science, you’ll probably get little of value from this thesis (perhaps other than just to reflect on someone else’s very different methods: building systems and doing mostly qualitative work). You might enjoy cross-perception, but I have a feeling it is too technically-focused to really pique the interest of a “pure” cog/perceptual scientist.
That being said, the slightly-more-critical parts of my dissertation (which I enjoy the most) are found in the introduction (1.1/1.2) and discussion sections (9.1-9.3). That might be good for the critical folks, theorists, ethicists, humanities-oriented researchers, and proper “sexy murder poets” of the field to check out.
System-builders might get value from reading data navigator, skeleton, and softerware. Maybe the whole thesis, too, to be honest. I’m this kind of researcher, so it’s all generally written with myself in mind.
Data people might really love data navigator, specifically if you enjoy data structures and graph theory. It’s graph theory, but for an HCI/systems/UI software problem!
Interaction design researchers might really enjoy the hardware work I did in cross-perception. You folks love when electronics and hardware work sneaks in. And some of our field’s existing hardware work actually has potential for accessibility work!
Purely graphic designers should probably check out chartability, to apply to your own work. Skeleton isn’t a bad chapter either, since the whole idea is that we apply visualization to an accessibility problem.
You probably know my work from the main chapters (my 5 papers), but you can skim them if you want. There are some exciting new pieces in there too, that I have recently submitted for publication. You might find chapters 6 (skeleton) and 7 (cross-perception) the most interesting, as they are my latest pieces. You might also benefit from at least skimming my introduction section 1.1: is “accessible visualization” really an oxymoron?
I’m tempted to say you should just read the whole thesis though. You’re probably among the two dozen people in the world at our intersection and if you aren’t familiar with my work or why I do it, then it’s certainly going to be enlightening as a reflection on your own work.
]]>You’re welcome to attend my thesis defense!2026-04-09T00:00:00+00:002026-04-09T00:00:00+00:00https://www.frank.computer/blog/2026/04/defense-inviteGreetings! This is an invite to attend my thesis defense, which is a public, hybrid-friendly event. This event will not be recorded.
Details
April 29th, 2026 at 12pm noon Eastern Time
In person (NSH 4305) as well as on zoom (zoom info in calendar link below).
There will, of course, be refreshments and snacks at the event. Please feel free to invite others whom you believe might be interested in attending.
Woah there folks! I guess google calendar has a limited number of people who can sign up to a calendar event. Use this zoom URL (intentionally not encoded as a link, to avoid bots) to join at noon EDT on April 29th:
(Replace [DOT] with . in that link text, of course.)
The talk is expected to be 45-50 minutes, followed by anywhere between 15 and 30 minutes of questions. We will likely start a couple minutes after the hour (turns out many wizards are, in fact, often late). You’re welcome to attend any part of the event that interests you.
My thesis is titled, “Tool-making as an intervention on the accessibility of interactive data experiences” and focuses on my research studying tools at the intersection of data visualization and accessibility.
My committee
(This is my council of wizards, who will decide my fate. They are some of the most powerful wielders of magic in the world, in their respective disciplines!)
This is a mystical event where a council of wizards decide if I am worthy of ascending to wizardhood myself. The process is relatively simple: I give an oral defense (a talk) regarding the contents of my dissertation, which is a document that represents the research journey I have taken during my PhD. At the end, the council (my “committee”) interrogates me with some questions, and then we open the floor for questions from anyone in attendance. After that, the public part of the event concludes (everyone is kicked out, including me) and the council makes their final decision. At the end, they let me know what they’ve decided. If they decide that I pass my defense, this is generally considered the point where I complete my PhD and become Dr. Frank, the Wizard 🎉 (we technically still have paperwork to do, but that is for the mystical bureaucracy).
Should you attend?
Hah! Have you been to one before? It’s a proper, ancient ritual. It can be neat to see a thesis defense at least once in your life. Will I get fried by a high level spell? Which magic will I choose to defend myself with? You won’t know unless you attend! But if you’ve been to several thesis defenses before, or you have no interest in the business of wizards, then you’re absolutely welcome to skip.
What is the thesis about?
My core argument (the “thesis statement” at the heart of the dissertation) is this: “This dissertation argues that the tools practitioners use to build interactive data experiences are themselves sites where accessibility barriers are produced, prevented, or alleviated for both end users and authors. This work contributes five tools—Chartability, Data Navigator, Softerware, Cross-perception, and Skeleton—that collectively center accessibility work on the empowerment of disabled and non-disabled practitioners across the full arc of evaluation, data navigation, analytical interaction, and personalization.” My work is interesting primarily because I argue that the work practitioners do is a rich site for research. I don’t just make a proverbial “hammer” but study what sort of hammers we need, whether hammers really work, and then how people actually use them.
Should you read my dissertation?
I highly doubt it! But that being said, there are some pretty fun parts in it, worth a skim (depending on who you are). For the most part, my dissertation is a “stapled paper” type of thesis, where the bulk of the document is comprised of my top-papers (that are the projects I personally led and executed) inserted without editing as the main “body” chapters of the dissertation. Then, the thesis itself generally has (up front) an acknowledgements section, introduction, overview of contributions, and (at the end) some kind of summary/discussion as well as a biographical sketch.
🤓 📚➟📖
I’ve generated miniature versions of my thesis document, to make reading easier! The basic document has 142 pages of content. That’s a lot! But I wondered… would more people actually look at my thesis if the page count wasn’t so intimidating? (See below sections for these mini-docs.)
That being said, many folks may want to check out one or some of the sections in the dissertation without having to read all of it. So here are some suggested readings for folks I know who are of different kinds:
Anyone who attends my thesis defense should probably check out my acknowledgements section. You’re probably in there! If you aren’t but think you should be, let me know!! I am terribly forgetful and would hate to leave out a friend, colleague, or supporter.
It also might be worth it to skim my biographical sketch, especially because the introduction to it pokes fun at many other bio sketches where people love to point out their origins as a genius child in high school who then ascended to harvard/MIT/etc; brilliant because of their own individual genius, of course. By contrast, I have largely been an unremarkable and unaccomplished person. I was a terrible student in high school and mostly didn’t “deserve” or earn the opportunities I had in life. And yet I did remarkable things regardless, mostly thanks to all the folks who have helped me out over the years. I hope my biography is a testament to the power of social support and that I have never really been a “main character” in my life. (Note that my own advisor joked that he wished he had paid more attention to my PhD application, because my undergraduate closed and I did poorly in high school. I probably shouldn’t have been admitted to CMU, haha. He is certainly from a “real” academic and technical pedigree; he would know!)
2. You are a technical practitioner of some kind (non-researcher)
I’d recommend that anyone technical (whether a designer or developer) checks out 1.2, 9.1, and 9.3. Pretty much everyone who works with “tools” (including AI/genAI/LLM/ML tools) should check those out (as well as my blog post on tools.)
You are specifically an accessibility practitioner
Definitely read 1.1 of the introduction because it has a way of thinking about accessibility work that everyone doing any accessibility work should consider: is “accessible visualization” really an oxymoron?
I think that academic papers can be awkward to suggest, but I genuinely think that if you check out any main chapter, you should read the one on skeleton, since it is about making accessibility work more accessible for sighted practitioners. A lot of accessibility work is (ironically) inaccessible! We should change that. Chartability is another good read along those lines, too.
Absolutely read 1.1 of the introduction: is “accessible visualization” really an oxymoron? I wrote that with visualization folks in mind. There have been some tricky, even subtle ableism in our field that I wanted to clear up before outlining my work. The part where I engage misconceptions about accessibility is worth reflecting on as well as the part where I outline what visualization is actually about.
I think that academic papers can be awkward to suggest, but I genuinely think that if you check out any main chapter, you should read the one on skeleton, since it is about making accessibility work more accessible for sighted practitioners. Chances are: that’s you. I also think that softerware should be a chapter that anyone who builds or designs visualization systems and tools should think about: how do you enable end user personalization?
3. You are an HCI/HAI/visualization/accessibility/”tools” researcher of some kind
All researchers will probably benefit from at least reading chapter 3 (my overview of contributions) and my final section, who is responsible for repair? Read those in addition to any subsection below that applies to you:
I think the introduction (sections 1.1 and 1.2) as well as the conclusion’s sections on what is a tool? (9.1) and applied accessibility research (9.2) are especially valuable, and hopefully provocative. I’ve done a good job if a few people from the ASSETS community are flustered about 9.2, in particular.
You might want to do more practitioner-focused work (or have an interest in this), in which case I’d recommend skeleton, chartability, and softerware especially. Read data-navigator if you want to get mad that I didn’t run a user study to validate our system (challenge mode: think about whether this kind of work is valuable or not in/for accessibility research as a broader discussion).
Absolutely read 1.1 of the introduction: is “accessible visualization” really an oxymoron? I wrote that with visualization folks in mind. There have been some tricky, even subtle ableism in our field that I wanted to clear up before outlining my work. The part where I engage misconceptions about accessibility is worth reflecting on as well as the part where I outline what visualization is actually about.
But “visualization researcher” is a funny categorization to me. Visualization research has cognitive and perceptual scientists (our “real” science-doers), feminist and critical theorists, ethicists, interaction designers, system-builders, graphic designers, data people, and applied researchers. My thesis is mostly written from the perspective of system-building and a little bit of interaction design.
If you’re into cognitive and perceptual science, you’ll probably get little of value from this thesis (perhaps other than just to reflect on someone else’s very different methods: building systems and doing mostly qualitative work). You might enjoy cross-perception, but I have a feeling it is too technically-focused to really pique the interest of a “pure” cog/perceptual scientist.
That being said, the slightly-more-critical parts of my dissertation (which I enjoy the most) are found in the introduction (1.1/1.2) and discussion sections (9.1-9.3). That might be good for the critical folks, theorists, ethicists, humanities-oriented researchers, and proper “sexy murder poets” of the field to check out.
System-builders might get value from reading data navigator, skeleton, and softerware. Maybe the whole thesis, too, to be honest. I’m this kind of researcher, so it’s all generally written with myself in mind.
Data people might really love data navigator, specifically if you enjoy data structures and graph theory. It’s graph theory, but for an HCI/systems/UI software problem!
Interaction design researchers might really enjoy the hardware work I did in cross-perception. You folks love when electronics and hardware work sneaks in. And some of our field’s existing hardware work actually has potential for accessibility work!
Purely graphic designers should probably check out chartability, to apply to your own work. Skeleton isn’t a bad chapter either, since the whole idea is that we apply visualization to an accessibility problem.
You probably know my work from the main chapters (my 5 papers), but you can skim them if you want. There are some exciting new pieces in there too, that I have recently submitted for publication. You might find chapters 6 (skeleton) and 7 (cross-perception) the most interesting, as they are my latest pieces. You might also benefit from at least skimming my introduction section 1.1: is “accessible visualization” really an oxymoron?
I’m tempted to say you should just read the whole thesis though. You’re probably among the two dozen people in the world at our intersection and if you aren’t familiar with my work or why I do it, then it’s certainly going to be enlightening as a reflection on your own work.
]]>On genAI: Was prototyping really a bottleneck?2026-03-09T00:00:00+00:002026-03-09T00:00:00+00:00https://www.frank.computer/blog/2026/03/prototyping-bottleneck(This post is a part of my new mantra moving to Cal Poly SLO: “move SLO and repair things,” which is in direct tension with the mantra from the tech industry “move fast and break things” as well as a play on the abbreviation of San Luis Obispo, where I will soon work. I want to cultivate a research culture and lifestyle focused on maintenance, careful deliberation, and care, as defined in the feminist sense of the word.)
Ever since ChatGPT, folks have frequently remarked something along the lines of, “LLMs are so fast, now we can easily scaffold prototypes! Finally, the bottleneck is gone!” Bottleneck? Was the problem with prototyping the fact it took too long? Some nerd (Microsoft guy maybe?) said the even-more-ridiculous “finally the bottleneck from typing is gone” as if the speed of typing is what was holding back new ideas and features and improvement and so on.
⚠ Warning:
This blog post is a response to a post on LinkedIn. The original may someday be lost in time! For now, the post is here, by Enrico Bertini.
Enrico writes,
“I am convinced we are in a new era for Visual Analytics (VA) (i.e., visual interactive data interfaces), but I am not sure we have yet realized it.
In VA, building and refining a prototype has always been a costly bottleneck. This is no longer true. A single skilled person can build a working prototype in a matter of hours. They can also thrash it and rebuild it within hours. Heck! They can even build three alternatives and show all of them in maybe 1-2 days. This is no small change. It’s massive.
How do we deal with that?
All of a sudden, an idea in my head can be transformed into a tangible prototype very quickly. This has enormous implications for applied research. If I work with a partner in a specific domain, I can quickly show something rather than talk. If I am good enough, I can even build something they can use pretty quickly.”
I don’t want to interpret Enrico’s words too harshly or in an ungenerous way (but I could, if this was all I saw!). I think Enrico has remarked in the past on many occasions that genAI is creating new challenges. And I want to unpack some assumptions I see here in this post, as well as assumptions (and dangerous ones!) that I’ve seen many other people express.
One of the main challenges, before I really jump in, is that building something quickly can be good if you know exactly what you are doing. And this is the danger! Students haven’t learned all kinds of things about software and how to think about users, human cognition and perception, and more. And non-technologists are often unopinionated about the detailed design and engineering intricacies that someone who is more-experienced in technology comes to consider.
But people tend to assume that the ideas they have in their head are really good, if they aren’t used to rigorously iterating on ideas.
Sometimes… slowing down is good for you, the builder! And sometimes going fast is awesome, but you must absolutely know what you’re doing. (And at that point, genAI is very-rarely much of a speed-boosting tool. GenAI users tend to spend far more time checking output and logic compared to when they write code themselves.)
So, consider this blog post a response to the least-generous interpretation that one might have of the world around us; peering at the worst-case scenario uses of genAI and not just the optimistic ones.
Artifact refinement versus idea refinement, and how prototyping fits in to the picture. If you believe that prototypes are merely an idea made manifest, rather than prototypes representing a means to refine the ideas they represent, this diagram might help you realize a few things. (Namely that folks often assume what they lack are skills, when they often lack skills AND well-refined ideas...)
Is iterative ideation itself a bottleneck?
In some contexts, slow prototyping is probably a “bottleneck,” sure. But prototyping is central to generating an understanding of the thing you’re making, questioning your assumptions, and trying to communicate the rawest components of your ideas. None of those inherently get better if you do them faster.
In terms of prototype “fidelity” (understood as “faithfulness”) I reckon we need to now consider: whose ideas is this prototype faithful to? Is this prototype faithful to the original human creator, or are there embedded biases in this prototype’s function and construction because it was made using agentic tools/modern models?
An “unfaithful” prototype now has a new meaning, because we can more easily create prototypes that appear to be high fidelity, but may not actually be faithful to the intricacies of any particular idea at all.
This line below, in particular, I think does have enormous implications for applied research, but I wouldn’t necessarily assume that the implications are all good:
All of a sudden, an idea in my head can be transformed into a tangible prototype very quickly. This has enormous implications for applied research.
I agree that a shift is taking place. But I don’t think we should just move forward as if the act of slowly prototyping itself was a problem to solve. I would argue that the act of prototyping (especially when done slowly) is still valuable as a necessary step we take as creators, attempting to make something new. (As a note, I get disappointed with the view that a “prototype” is the same as “a first attempt to create something” and not “an artifact I use to reflexively to discover+congeal my own ideas and communicate with.”)
Is faster communication… better?
I’ve written about prototypes before, and what I think much of our literature misses on the subject: that prototypes are actually a tool for communicating. (This blog post of mine on prototyping was my most-visited post, before my post on AI + Tools came out. Funnily enough, this post I’m writing right now seems to be marrying the two.)
The fact that we can communicate faster isn’t necessarily good, if we don’t have a firm grasp of the idea itself in our head in the first place. One of the best parts about prototyping, to me, are the slowest parts: you draw something out with a pencil and paper, you cut out pieces of cardboard, you use some lego bricks to scaffold something, you get up to a whiteboard with a few other people and start squeaking your pens across the blank canvas together… and you talk about that stuff with each other. I am in love with the feeling of new thoughts forming in my head. A thought coming into being? Boring. But an existing thought refining and honing and strengthening? It’s beautiful.
“Prototyping” is not a linear pipeline that goes from an idea in your head into a material artifact that represents that idea.
Prototyping is a method of symbol-making. And we use those symbols to communicate ideas.
And this is why I am actually worried about prototyping that moves too fast. And in fact fast-prototyping-as-a-problem isn’t new! Researchers who studied “fidelity” in prototyping have long discussed how moving too quickly to higher fidelity prototyping can bias your future ideas, bias your outcomes, and ultimately produce more costs, not less, down the road (see this seminal summary of the great older battles on fidelity by Rudd, Stern, and Isensee).
Are genAI prototypes anti-social?
So back to Enrico’s argument here… I’m not sold that faster = better and certainly not sold that faster = better = cheaper (specifically responding to the sentiment in his post that it has “always been a costly bottleneck”). I think that existing literature would argue quite the opposite. To me, there are three dangers with going too fast: Faster = 1) more assumptions are missed in the core ideas because you have less time to validate and test fundamental bias, 2) ideas that appear already-refined become immune to questioning because they appear to be already-solved problems, and 3) less time spent socially co-constructing.
Yes! You heard me: Faster prototypes can become anti-social prototypes. This final point (which I am making, not necessarily something I’ve read in the literature on this) is actually the most important one to make: prototypes are about symbol-making for the purpose of communicating. Forming an idea with others is one of my favorite activities on this earth. We’re making meaning together! How beautiful is that? Not only do we create things together, but through the process of co-creating meaning, I find myself. I gain a sense of individual and collective identity through co-creation.
I don’t just order a meal and a chef prepares it (which is the genAI design model: you, the customer, and the model, the service). Instead, I learn that I, myself, by taking action to sate my hunger can become a chef-in-training. By learning new ingredients, by learning how to operate tools, and through trial and error… I can gain a sense of identity beyond the customer-consumer that genAI companies want me to imagine for myself. And the best part of the self-discovery process? My partners become my line cooks, sous chef, wait staff and so on. We form a team around this new idea we create together. Why would I ever want a machine learning model to replace the social aspects of making? The greatest privilege of creation is finding yourself in the people you co-create with.
But even selfishly: If you were the only person left alive on this earth, yet you still learned how to speak, you would likely not lose your internal dialogue. You would still speak, even to yourself, to think through things. And prototyping, as an act and process (not a destination), is about that symbol-making. You’re working through whatever idea needs forming and needs new symbols for expressing. Prototypes are a form of self-socializing ideation. And their inherently symbol-rich, generative nature makes them ideal for socializing with others.
Enrico acknowledges the power of socializing in his post:
“If I work with a partner in a specific domain, I can quickly show something rather than talk. If I am good enough, I can even build something they can use pretty quickly.”
And here is the danger: sharing something with others that is too polished is exactly what existing literature on prototyping warns about! You’re sharing an over-developed set of assumptions! People mostly give feedback on little cosmetic details once you show them something pretty far along. And this behavioral barrier can be overcome with a good conversation partner (who might understand that what you are showing them is potentially throw-away), but this is unsupported by current literature that observes how people interact with prototypes (that generally people, if unprompted, will give less fundamental, high-level critique and engagement if the prototype is more-polished).
Inviting someone to write a language with you is different than asking someone to critique a sentence you wrote. What you want, when socializing a prototype, are conversation partners who want to question your core assumptions about whatever problems you believe exist and are trying to solve. Prototyping that is low fidelity (and slower) invites this language-crafting level of engagement with peers. Higher fidelity (with LLM assistance or otherwise) invites a copyediting level of feedback. We want socialization on the core symbols and ideas we choose to construct! And that might always have a human bottleneck built into it (for as long as we humans are in charge of prototyping, that is).
Socially constructing meaning is slow (and good!)
But just to drive this home: socializing your idea is the real value of a prototype. Socializing a raw idea is a fundamental epistemic activity that we do. The philosohpical existentialists and absurdists spoke to this: existence precedes essence. We give the world around us essence. We, the collective subject that is humanity, assign meaning to the world. Prototyping is a radical, social act of communal meaning-making.
And I honestly wouldn’t like ideation, as this quintessentially human act, if I only ever did it alone or with a machine that simply confirms my biases and listens to my instructions. Refining, discussing, sharing, mixing, appropriating, and fusing ideas are actions that really only come into the picture once we have a prototype in between a few people who are trying to figure something out together.
But why is socializing so important? Because our intelligence is positional and situated. We have “horizons” of knowledge, and limits, as singular beings. We are not objective. Yet through social inclusion in the act of making and forming ideas, we broaden the angles and horizons of our social constructs. And for this reason, prototypes that are socialized are simply better, more meaningful creations. I’d even argue that a prototype that isn’t socialized isn’t a prototype at all, it is just an early attempt at making something: the focus is on the object being made, not the idea it represents. And it’s that human socialization and collective meaning-making that turn an artifact-in-process into a prototype that is refining something outside of itself: an idea-in-process.
In “what do prototypes prototype?”, Houde and Hill argue that the separation of artifact and idea is key to understanding the value of prototyping: the prototype isn’t the idea itself, it is just a symbol of the idea (hence, why I write about why fidelity = faithfulness and not something like “quality”).
I worry about prototypes that are too refined too soon. Will they alienate our ideas, because our ideas are less inviting for critique/reshaping at fundamental levels? (Isn’t it ironic, that using a language model possibly holds us back from building a truly social new set of symbols for communicating an emerging, shared space of thinking?)
A good prototype can be made quickly, but it needs to be a little bit shitty, too; it’s basically a requirement. And in terms of pure speed, the fastest prototypes I’ve ever built are still far faster than an LLM-prompted mini-app and contain far fewer baked in patterns and assumptions about what I’m trying to accomplish. The humble pen and paper, cut out pieces of paper, and lego brick styles of prototyping are all undefeated ways to build a shared set of symbols about a new idea with someone. Plus, they’re fun to collaborate with, as a design material! Until we can have easy to use, small, modular, generic, programmable soft and hard materials, doing things with smoke and mirrors and little trinkets is still my favorite way to do things.
Anyway, this blog post is a largely-unstructured brain-dump in response to a linkedin post. Thanks to Enrico for posting it! It certainly got my juices flowing.
And it does seem ironic to me to socialize the idea that prototyping=faster=cheaper=good (that all of these things are true and related). That seems like an idea that has been developed too far… it has too much fidelity, not enough prototyping. Perhaps I would recommend going back to the drawing board and re-assessing this?
Bonus take: the psychology of faster = better
Now, the real spicy take of mine (imagine the armchair psychologist within me saying this): I don’t think the “bottleneck” that existed was any more than simply manufactured human impatience. We don’t want fast because fast is actually better or cheaper. We want fast because someone convinced us that fast feels more secure. We have been told that fast feels stronger; feels productive. Fast makes the line go up and lines going up is a good thing.
But fast is affective and subjective more than it is objectively good. We have socially constructed why time matters and by extension we have socially constructed why faster things matter. And so the objective speed of something is actually secondary to our perception and understanding of speed. As anxiety-ridden animals, we have invented the want for things that appear fast, even if (by actual measurement), things can be just the same speed or even slower.
We are taught not to like that our ideas and symbols are in-process, fragile, and flimsy… and that we have to sit with that reality for a while before making something good and meaningful. We want our ideas and symbols to appear as-congealed as possible as quickly as possible. Binary gender suffers from this problem! “Man” and “woman” are so strong and congealed and total and without nuance. Yippee! We are safe from fluidity now, so long as we ascribe to a gender binary!
And so large-language models give us performative fidelity; a sort of false, constructed faithfulness to ideas we haven’t actually invested enough time into and haven’t socialized. If anything, they construct loyalty to under-formed ideas more than they actually construct ideas, because constructing ideas is slow and messy!
Large-language models then simply become yet another social function of anti-fluidity, seeking to box up a thought as soon as we have it and transform that thought into a commodified, less-flexible unit, which we can claim is an “idea” that has been “prototyped” (without any symbol-making and socialization necessary!). This brain-fart-to-built-UI pipeline is so fast that it might actually begin to convince people that their lightly-sautéed neuron-events are actually really well-thought-out, mature concepts; like slapping sheepskin on a lamb.
“Prototyping is faster now” is yet another example of the make-you-feel-less-insecure style of marketing that every modern company dreams of taking advantage of. Marketing sold us the need for deodorant by stoking human insecurity, and now it’s working on the impatience and insecurities of software engineers, too.
]]>5 reasons why I didn’t choose an R12026-02-18T00:00:00+00:002026-02-18T00:00:00+00:00https://www.frank.computer/blog/2026/02/say-no-to-R1sI cast a wide net this job market season. I wasn’t sure where the jobs would be, and I was pretty confident that things would be competitive (since the state of industry means more people who are on the fence about industry might become tempted by faculty positions). And the state of the US means that faculty positions overseas, I reckoned, would be especially competitive.
But I’ve been planning to get into academia since I left industry in 2021, so I wanted to really examine all of the pros and cons of the different styles of academic life I could end up living.
Research staff at an R1: I had already done research staff work back in 2017 and 2018 at Northwestern, and I wasn’t interested in that lifestyle. It didn’t pay great, but also had no job security (I survived a big culling they did in 2018, but that motivated me to look for employment elsewhere - if the pay is lower than industry but I’m still treated as expendable, like an industry job, then why stick around?).
Research scientist at an R1: I could have looked for the few “research scientist” roles, at places like CMU, Stanford, and so on, where you just do research 24/7 and have your own grants and agenda, but the problem with those is that you have to have a very high output level before starting, which I don’t have. And pretty much all of the openings that I saw explicitly prioritize AI/ML research over everything else (because, of course, that’s where the money is at 🙄).
TT research faculty at an R1: Now, the tenure-track (TT) research faculty roles at R1s are tempting to me. You get tenure. That rules. And the bar for research output is lower than a pure research scientist role. And the bonus? You are expected to teach a little bit. (I love teaching.) This all seems great! And I’m sure that in an optimal environment, an R1 could be a good fit for me. However… let’s break down a few reasons why this kind of work isn’t ideal for what I want:
5 reasons that TT research faculty roles at an R1 aren’t ideal for me, personally
1. Funding
The biggest reason that R1s became less of a priority to me happened due to all of the cuts in 2025. I watched the folks who do accessibility research at UW, UC Irvine, U Mich, and many other places lose funding. Stacy Branham, one of the people I look up to the most in our little corner of the world of research, who was the co-PI of the single-most impactful grant in accessiblity research in computer science (called AccessComputing), announced last year on Linkedin that the grant did not survive federal cuts.
Research faculty positions at R1s are expected to produce significant amounts of research. If you look at the incredible career of Jen Mankoff (my absolute favorite person who does accessiblity/assistive tech/disability studies research), as an example, she has authored over 200 papers in the last 2 decades or so. In order to be this productive, you have to advise PhD students, whose entire “job” (aside from taking classes) centers on a joint pursuit of your research agenda and their own.
Research faculty need PhD students. And they’re very expensive because of how higher ed works: admin takes a big cut of all your grant money, and then you also have to pay significant premiums for the cost of your PhD student’s education. Some PhD students cost as much as 140,000 USD per year!
But with fewer opportunities for funding, especially since my entire agenda centers on inclusion of people with disabilities in data science work (which is an area the current federal administration has obliterated), that means that I will be under significant pressure to put out papers but might lack the students to help me accomplish my goals. I need to get tenure! But fewer grants means a worse tenure package and fewer grants also means fewer students, which means a lower output level. Not good! I don’t want to work 60, 70, 80 hours per week just to compensate for the state of things, most of which are beyond my control.
And the worst part about having fewer funding opportunities? I would need to consider if my soul was worth selling out… should I look to defense funding? Should I bring the claws of corporate capitalism deeper into the academy than it already is? Mols Sauter shook me up last year, essentially letting me know that my existing corporate relationships make me out as someone basically already on the road to being an academia-destroying poser. (Mols was much nicer than this, of course, but the reality is that I’ve already demonstrated I’m willing to partner with powerful companies who have profit-based incentives in order to do my work. This does, to some degree, participate in the “corporate capture” of academia, threatening the spirit of true research activities.) And as an aside, Amy Ko (who I look up to immensely) had called me “very corporate” at SIGCSE’s workshop on accessibility just about 1 month and a half previous. I basically evaporated when she said this to me. (I needed a little self-awareness awakening, in this regard.) So by the time Mols brought into question my tenuous relationships with industry, I was already reeling hard from impostor syndrome and self-doubt in terms of both how “pure” I am as a researcher and the actual ethical impact that alternative funding has had on academia.
And, as a little extra anxiety here: If I wanted to get a grant in accessibility… I now have to compete against the Stacy Branhams and Jen Mankoffs of the world, who are all also trying to get these big-dollar funds to help support their now-unfunded or under-funded armies of PhD students. I’d actually feel bad getting big grants, because there are real PhD students who need the support right now, as opposed to theoretical, future PhD students I’d hope to be able to support.
2. Underpaid workers
And speaking of PhD students… they’re grossly underpaid! I actually don’t recommend that anyone does a PhD unless they’re already unionized. CMU has been horrible and our 2 attempts to unionize have failed. I still believe in the cause, but the US Department of Labor is now in the hands of a very anti-worker set of people, whose agendas will certainly smash any new union efforts. It’s going to be very hard to get a recognized union built in the next 3 years because of Trump and his ilk.
So, I have to ask myself… do I really want to start a pyramid scheme? Especially one where the lower-order members of the pyramid aren’t unionized? If I actually wanted to run a top-down capitalistic scheme, I’d hope that my minions at least had fair pay and bargaining rights.
I actually left industry because of a closely-related issue here: the only clear path forward in my career was “up.” ICs (“individual contributors”) hit obvious ceilings of pay and freedoms, while people who take managerial paths forward end up continuing up and up in perpetuity.
But I don’t really like “managing.” I’ve even written extensively about how LLMs are essentially the perfect fantasy technology for managerial-aspiring people: you go from creating things to managing them. You cease to be a chef when you order from a menu. You cease to be an artist when you commission a piece. And I enjoy the act of research, building, making, and so on.
I don’t really want a pyramid scheme in my future research lab, but without material equity, any culture or “vibes” I try to set won’t prevail. PhDs need fair pay, fair treatment, and… I also want to get hands-on with the work sometimes. (Jeff Heer does this with projects like Vega and Mosaic, and I think his style of output would be entirely what I’d love to do someday, too. A mix of teaching/mentoring/advising… which is inescapably hierarchical due to a differential in expertise and experience, but also a mix of just doing things yourself, too, when you need to scratch the itch.)
3. Shallow evaluation of productivity
This does segue into my next topic: how I work plays a huge role in whether or not I hit tenure. I have been speaking to Niklas Elmqvist over the last couple years, who has repeatedly offered me incredibly insightful wisdom. He has been generous sharing wisdom on general European vs American academic culture, housing, work-life expectations, and a whole lot more. But he also let me know that European assistant professorships often expect more experience than just a PhD before starting. This is mostly because their PhDs are only 3 years, which isn’t quite enough time to really build out a research profile. So, it is common to expect a postdoc, or (in the absence of a postdoc) a higher level of research output than what a European PhD student typically has, to get your foot in the door at a European “R1” slot as an assistant professor. Niklas gave me great advice on leaning into my strengths and contributions outside of purely my research profile (such as my prolific industry collaborations, influence in policy spaces, and mature career as a respected name in visualization and data science communities outside of academia). While this advice was fantastic (and, spoiler alert, helped me land somewhere I am very happy with), it also helped me to temper my expectations of places that are not quite open-minded enough to really see these strengths of mine as valuable to the academy. I don’t intend to significantly shift how I collaborate with industry partners, nor do I intend to significantly shift the kinds of impact I cultivate in my work. For this reason, my “pure” research output has been on the lower side.
And postdocs are great, don’t get me wrong. But they weren’t a priority for me. Other folks have pointed out that postdocs help you get experience with different institutions, can help you get more funding opportunities, and also just pump out papers. On that last point, I had 2 separate European faculty tell me that a low h-index (like mine) may simply keep me from being considered at a lot of places. They may simply filter me out early on, just based on lack of numbers. (3 of the 4 European faculty I spoke to about job market stuff mentioned my low h-index… which was a much higher rate of mentioning it than outside of Europe. Australia, Asia, and LatAm folks didn’t mention it at all and in the US it was mostly about the “shape” of my current trajectory, which looks “good,” rather than the present state of my paper citations.)
But my point is this: h-index scores play a huge role in some circles. I haven’t spoken to faculty who take it seriously in a one-to-one conversation, but to hear that it plays a role in filtering out candidates who aren’t deemed “mature” enough, means that it is a serious metric, whether or not academics openly admit it to your face.
What is an h-index? Glad you asked. It is an abomination. It is an affront to anyone who wasn’t created in a test tube from birth and trained since adolesence to produce research papers with high citation counts. To put it simply, it is a rough measurement of your paper output and times your work has been cited. Google Scholar defines it as “h-index is the largest number h such that h publications have at least h citations.” So if you have 11 papers, all of which have 10 citations each, then your h-index is 10. But if your 11th most-cited paper hits 11 citations, your h-index becomes 11.
There are a lot of things wrong with h-indexes, from a pure stats perspective. But from my perspective, it is a measurement that incentivizes only activities that participate in that metric’s improvement. As someone with a long history in data science, this ends up having an effect where people who are otherwise good people who want to do good in the world, end up only really caring about producing research (and specifically producing research papers that maximize their citation counts).
Can you have a great research career without focusing too hard on your h-index? Of course. But this single metric has shaped the entire culture of research into an industry. Measurement is one of the most fundamental forms of social control. And h-index is about the consolitation of behavior and activity of scholars into paper-producers. Not great.
For me, h-index is especially not great. My h-index is 5. And I’ve been told that 7 is minimum for TT R1 research, but 9 to 15 is considered strong.
But I would not have done the work that I did, on Chartability or Data Navigator, if my goal was h-index pumping. I would have been a low-effort co-author on at least 5-10 papers led by other people, instead of working with policy organizations and ensuring that my industry peers actually leverage my work. I care about the real-world impact of my research, which ironically is what the h-index score ideally tries to measure! Yet, in the same way that jobs filter out candidates programmatically who don’t say the magic words on their resume, without a high enough h-index, I simply won’t look good enough for a TT research faculty position and will have a much harder time hitting tenure. I simply should not care about shaping how the European Commission, World Health Organization, New York Times, Apple, Adobe, and 150 other open source communities and organizations actually work to make their visualizations more accessible. I simply would just have to hope that I write papers, throw them into the void, and that the resulting “citations” is a good enough proxy for “doing good in the world.”
Now, to be clear: h-index at its best isn’t a metric you should try to game so much as just a way to observe your own progress as a researcher, specifically within the scope of paper output and citations. That is a helpful metric, when it is a tiny part of the overall picture. But it is also primarily only useful for people who manage you but don’t have enough time to listen to you talk about how your work is being written into official guidelines for the Government of France, or something. People want numbers and the h-index is already there, so for convenience it serves that small role.
Now, R1s love to talk about how they value other stuff. But basically, it all boils down to pumping out papers like a factory pumps out dongles and getting utterly loaded with grant money. It’s papers and funding, pretty much as the two major non-negotiables. And is there an expected minimum for either, when going up for tenure at an R1? Nope.
And that, my friends is the problem. If an R1 told you up front that tenure requires 18 papers with at least 18 citations (an h-index of 18) by the time you’re up for review, combined with an expected year grant award average of 500k over your first 5 years, then I’d be able to set healthy lifestyle expectations.
And R1’s rightly argue: we don’t tell you exactly how to get tenure because every academic is unique! Yes, that sounds perfect. Except that they actually only care about papers and funding and without a clear floor or ceiling set for expectations, you are incentivized to work towards papers and grants every waking moment of your life. Spending time with family? Taking vacations? Having hobbies? These activities are only useful if their utility “recharges” you (intellectually, socially, and psychologically) to go out and write more papers. Otherwise, you should probably be writing papers.
R1s, by nature of priding themselves on being at the top of the pack, have no clearly defined floor because they don’t want anyone doing “the bare minimum” at any point. Infinite work is part of the culture!
4. “You’re good at teaching” is a perjorative
This section will be short, but both people I TA’d for while at CMU (Scott Hudson and John Stamper) remarked that I was “good at teaching.” And at the time, I took that as a compliment. (I do genuinely believe that both of them meant it in a positive way.) But after discussing my goals and options with a bunch of folks (I asked many people for advice over the last 3 or so years) and everyone who wasn’t at an R1 spoke very highly of teaching and the value of education, while nearly everyone at an R1 didn’t mention it at all. And there were a couple cases where folks actually told me, “oh, those professors said you’d make a good teacher? They might have been telling you that you aren’t a good researcher. People will do that.” (Again, I don’t think Scott or John meant that at all, but the culture of teaching-as-perjorative in R1s is really disappointing.)
In Teaching to Transgress, the immortal bell hooks writes, “The classroom remains the most radical space of possibility in the academy.”
Teaching has been central to promoting my work to pracitioners, and also building relationships and collaborations. During my PhD, I’ve given over 100 talks, workshops, interviews, and guest lectures. And teaching students, I truly believe, is one of the most important things that I can do with my time and the knowledge I’ve accrued.
5. I’m not the main character of this story
That final note, on the radical value of teaching, leads me to my last point: I’m not the main character of this story (my “story” being the great quest to make data science, data visualization, and information in society more accessible for people with disabilities).
I’ve spoken about this before in several talks (see my keynote at DDD Brisbane, for example): At the start of my PhD, we took a class (essentially propaganda for doing a PhD and so on) about how you should frame your great research problems like a big quest and the villain (your “big P problem”) is a terrible dragon that only you, the hero of the story, can defeat using a mythical sword (which is essentially your chosen methodology and approach to research). You are encouraged to talk about your narrative as though you’re the champion who solves all the hard problems.
And this is a sickness at the heart of academia: believing this lie. The hero believes they are the only one who can defeat a dragon? Obscene. And in that class, we were encouraged to talk about ourselves within the “hero’s journey” and how we “overcame” the “graveyard” of other, failed researchers who tried to solve this problem (aka, like the “Related works” section of a paper, if you will).
This narrative accomplishes a few things. First, you come off as an asshole. And second, downstream from that (and the solipsism embedded in the narrative), you alienate yourself from others. Individualism was a useful framing, as situated in history. It helped us build language for autonomy, rights, freedoms, agency, and so on. But individualism is a state of deconstruction. Individualism only exists because, in order to see it, you must actively strip the subject of all meaningful connection to others.
There are many reasons that mental health during grad school is catastrophic (again, mental health being another reason that goes with point 2 above), but alienation and the forging of your narrative as a person who is, as an “individual,” the sole hero, is a huge part of that.
Why is being an “individual” problematic? Because to understand something as “a being that cannot be divided further” (what “individual” literally means), you must strip all other connections and relationships from a person and observe only what remains. For human rights, or concepts like independence, it is actually liberating to recognize that we have the agency to free ourselves from our chains. As a concept, it can be useful! “Okay, so individualism is good?” you might ask.
No. As I said earlier, it is a state of deconstruction. The “individual” is a thought project: useful in philosophizing “what if?” But nobody in reality is actually free from all connections and relationships. We breathe the same air as other organisms, we share this literal earth and its resources, and so much more. Nothing material and real is “an individual.” We construct this ideal state of a person because it helps us understand things like “autonomy” and “freedom” and so on.
But again: the state of the “individual” can only be understood as having been theoretically stripped of all connection.
So is the individual hero even real? No! The hero is a fantasy within a fantasy; made up. It’s only utility is in communicating some highly-congealed, super-concentrated narrative about our own contributions to the world. (And, to some degree, we should be able to understand ourselves as actually contributing to the world around us. It’s healthy to do that!)
But we shouldn’t be fooled: we are incapable of writing a research paper without language (requires people), technology to write (requires computers made by others), and without an audience (requires readers). The community the hero saves is actually fundamentally more important than the hero will ever be. The community orients itself and understands the dragon as a danger, the community is where celebration takes place when victories are won. The community, in most all fiction, is also where the hero finds a place to eat, sleep, and fall in love.
And R1’s want you to believe that the pinnacle of selfhood is individualism. This alienation drives you towards an undistracted, selfish pursuit of glory. The R1-mindset benefits from this! R1 culture hinges on “individuals” like this.
This is where things get interesting: Individualism, ironically, is a building-block for other social order to arrange itself. Because it is a state of deconstruction, hypothetically speaking, it invites us to imagine new social orders (or… spoiler alert, re-invigorate existing ones).
And this is why individualism is so dangerous: if you value yourself, as a disconnected entity from others, as the highest form of being, then you will gravitate towards ideologies that serve yourself over others. Individualism, because it is a state of deconstruction, demands that something is constructed after the strings and tethers that connect us to each other have been cut. And this is why academia has made itself into a pyramid scheme! The alienated worker becomes easier to exploit. Divide and conquer made manifest in the workplace! And whether R1 faculty are conscious of this fact or not, their productivity hingest on this meta-culture remaining in power. You need a “PI” who gets money and benefits from all of the research projects and work of everyone under them that they fund. They need to have that last-author position so their h-index can do big numbers.
But anyone who is reasonable, who breaks from this myth, learns quickly how important community, connection, and interdependence are. Because “individualism” is a state of deconstruction… we can construct better worlds than hierarchies and oppressive systems. And some R1 researchers do this! Really, I know of quite a few. Again, Stacy Branham and Jen Mankoff both seem to have been successful in an R1 role despite working for equity with their workers as a priority. But the industry that is R1 research doesn’t incentivize this. At large, you have to work very hard against the grain not to perpetuate these oppressive systems and still, at the end of the day, be “productive” as a researcher.
Ultimately, my response to the “hero” narrative has always been this: my whole career in tech, and even before (as a barista, organizer, service worker, carpenter, painter, and paper boy) was in support of others and their goals and lives. I’ve always focused on empowering what other people can do. I’m the blacksmith in the village who makes a sword that might be capable of slaying dragons… in the right hands. But do I slay the dragon, myself? Not a chance. And in fact, many other dragons exist. So part of my work as a toolmaker has been to think more in blueprints that other toolmakers can follow. This has been the focus and style of my work on Data Navigator, for example.
For this reason, being a toolmaker, teaching-centric environments also make more sense as well. I highly doubt I’ll solve the big P problems that I set out to tackle. But through teaching and mentoring, perhaps someone else will.
So… why take the path of most resistance?
Anyone at an R1 who looks at my profile next to a star like Franklin Li (my fellow lab mate and someone genuinely pulling it off with a higher h-index than many folks have before they even go up for tenure review), it would be hard to consider me a top candidate for an open position.
As I was assembling my job applications last Fall, I had to prepare myself for the reality that R1s will likely not even select a candidate like myself (I had early interviews at 2, but didn’t move forward). I also had a fast, early rejection to Uni Vienna. An insider let me know I was soundly beat by people with many, many papers published and millions in grant money raised already. I simply do not have enough traditional research output under my belt to even get on the radar of place with high research output. And these rejections (or not even recognition enough to reject… more like neglection for most of them), became a signal that this is likely not be the sort of environment I’d want to get into anyway!
If I want to create a world where I can do hands-on research, minimal “management,” have opportunities to demonstrate my impact in more meaningful ways than simply papers/citations/grant money, promote and cultivate an environment where people who work for/with me are treated more fairly (and this is structurally incentivized), and ultimately produce students and mentees who are equipped to go out in the world and make it a better place… then an R1 is not an easy path.
This is why I’m thankful for a tiny little slice of universities and colleges called “PUIs” or “primarily undergraduate institutions” that still expect faculty to do research and have a research agenda. The research-focused PUIs, which you can learn more about from this fantastic tool/blog by Evan Peck, have been my priority this season.
One person who gave me immensely helpful perspective, nearly two years ago, was Ken Holstein. Ken is among the best. He is faculty here at CMU and is massively productive as a researcher. He is truly a top intellectual in his field. But I looked at how much he worked, writing grants, constantly managing things, and so on, and wondered if that was really the sort of life I wanted to emulate. Picking his brain helped me peek into what life has been like for him in his first few years as an assistant professor.
And I was already curious about PUIs, but Ken let me know that a colleague of his recently started as an assistant professor at a little liberal arts college (doing research and teaching) and was “now living their best life.” Their work-life balance seemed to be far better to me than pursuing glory. (And again, no offense intended for folks that do! Really, if I thought I could pull off a career like Ken’s or Jen’s or Stacy’s, then I’d really be willing to give it a shot.)
(As a takeaway, if you’re considering an academic life and wrapping up a PhD, speak to folks who are research staff, teaching faculty, and research faculty at a variety of institution types, like R1s and PUIs, in a variety of contexts, like domestic and abroad. Because of this, I had a much better sense of what I figured would work best for me and the life I want to live. Again… individualism is a myth! I wouldn’t have made my own decisions if I didn’t have a whole community of people rooting for me and helping me to succeed.)
My big announcement: I’ve accepted my dream job
Cal Poly! I'll be an "assistant professor of data science."
So I want to now officially announce that I’ve accepted a job at Cal Poly (California State University Polytechnic), in San Luis Obispo. It’s a PUI that expects research. It ticks every box I could want. The faculty there have had outstanding research careers, yet the top priority for my tenure evaluation will be on my teaching. People clearly explained that I am evaluated based on having 2 “externally recognized” contributions per year: one might be a peer reviewed paper, another a grant, but I can also get creative (but they let me know the floor!). The master’s students and undergraduates I would be working with are top notch, the pace of life is far more balanced than an R1, and (through my interview process) it was abundantly clear that both my past industry career and my a-typical avenues of impact are highly valued.
That last part sold me on Cal Poly. Stephanie Valencia Valencia, over at UMD told me to “go where you are celebrated” and that “you will know once you’re there if you are or not.” Faculty and the students at Cal Poly saw my industry experience and style of collaboration as a huge benefit to the university. And folks with impressive research agendas spoke very highly of the level of maturity and breadth of impact from my research. It was clear to me that, unlike the R1s I had interviewed at, my past and present styles of work were considered an actual benefit. (Again: I wasn’t created in a test tube and cultivated from adolescence to produce top-cited research papers… I have a broad and varied background. It felt good to be seen for that and valued.)
I am a bit melancholy, to some degree, that I am not a more-typical sort of researcher with a typical profile of research, style of work, set of politics with workers, and arrangement of interests. I would have loved to imagine myself as the hero who slays the dragon at an R1 and gets all the glory. But that isn’t me. I’d be living a dishonest life if I thought that was even what I really wanted, too.
So here’s to a new adventure and embarking on this next arc of my story.
And I am quite thankful that the next arc of my story is back on the west coast. The smell of the Pacific? The seafood? The mix of cuisines and culture? Oh... and temperate weather year-round? Immaculate.
Oh and special thanks to Dominik and Patrick, my advisors. They’ve both been nothing but supportive of me and my goals. I’m thankful for them (and Ken and Jen, both also on my committee) for being so generous with time and advice.